• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Report

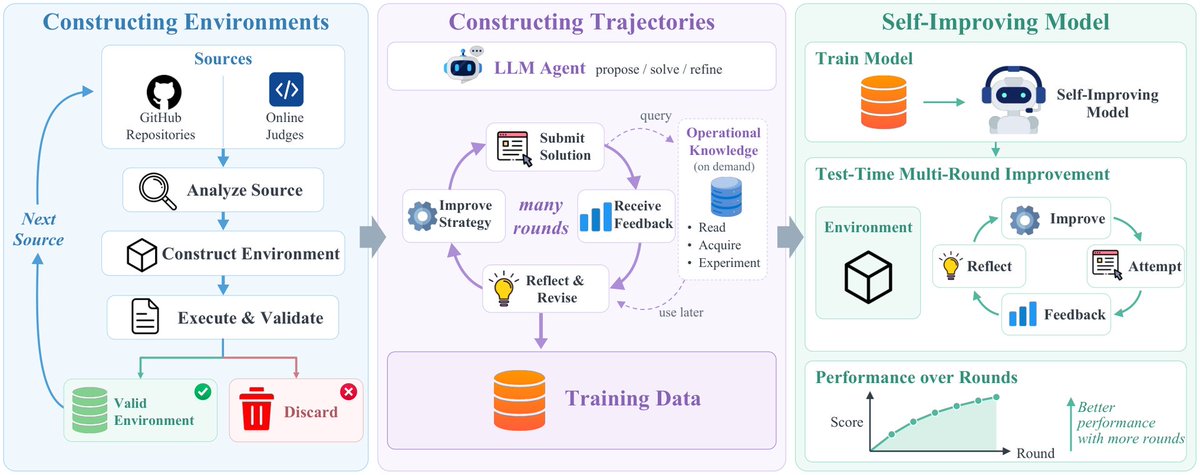
    AREX-2 is claimed to improve solutions with more test-time rounds

    HuggingPapers describes the 27B agent as trained on verifiable machine-learning and algorithmic tasks.

    AK
    DA
    2 Sources, 8h ago, first seen 8h ago

    TLDR

    HuggingPapers says AREX-2 improves its solutions with more test-time rounds. It reports scores of 81.8 on MLE-bench Lite and 70.7 on Frontier-CS, and says the agent transfers to deep research.

    Combined views

    3.7K

    2 Sources, first seen 8h ago

    21 likes
    Combined views

    3.7K

    2 Sources, first seen 8h ago

    21 likes
    5 comments
    10 saves
    7 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    5 comments
    10 saves
    7 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    @HuggingPapersAREX-2: Advancing Self-Improving Agents through Long-Horizon Reflective Tasks A 27B agent that turns more test-time rounds into better solutions, trained on verifiable ML and algorithmic tasks. Achieves 81.8 on MLE-bench Lite, 70.7 on Frontier-CS, and transfers to deep research.
    @_akhaliqRT @HuggingPapers: AREX-2: Advancing Self-Improving Agents through Long-Horizon Reflective Tasks A 27B agent that turns more test-time rou…