Report
In a 12-model test, AI judges chose their own answers more often than human voters did
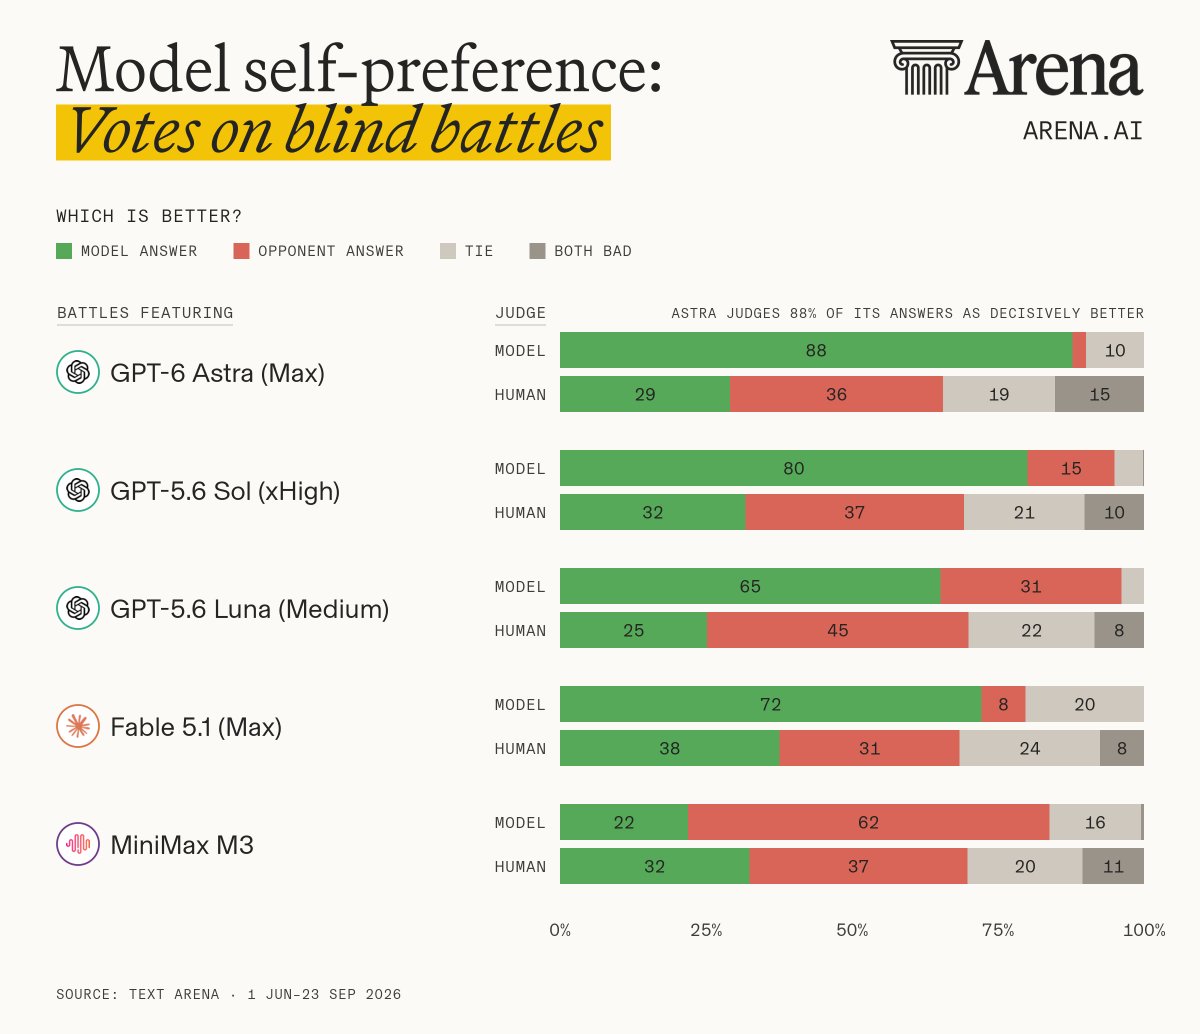
Arena says it compared 34,580 model verdicts with human votes across 1,460 battles. On average, a judge chose its own answer 58% of the time, while people chose that same answer 34% of the time.
TLDR
Arena reports that it asked 12 models to judge Text Arena battles without revealing which model wrote each answer. On average, a judge chose its own answer 58% of the time, compared with 34% for people choosing that same answer. When both the AI judges and human voters picked a winner, judges agreed with other AIs 79.4% of the time and with the human voter 56.9% of the time. People called a tie or “both bad” in 32% of battles; GPT-5.6 Sol picked a winner 96% of the time.
Combined views
52.4K
2 Sources, first seen 4h ago