• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI

    MIT Researchers Study Dynamic Compression for RNNs

    MIT researchers examine dynamic compression to let RNNs revisit and reorganize memory states during sequences.

    SA
    AZ
    JP
    4 Sources, 41d ago, first seen 41d ago

    TLDR

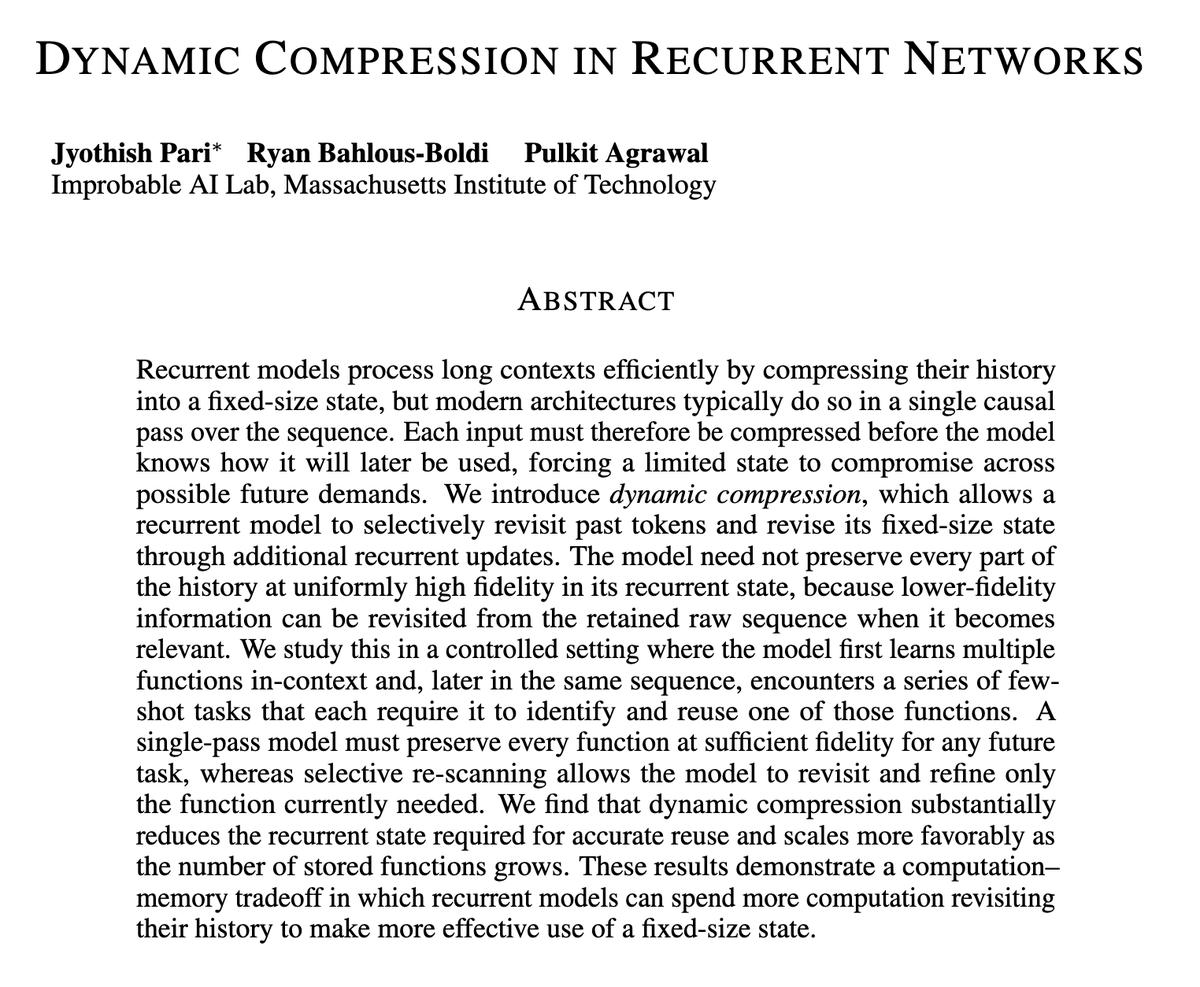
    Jyo Pari described in-context continual learning as requiring models to accumulate experience and reuse it later in the same sequence. Standard RNNs compress an ever-growing history into a fixed-size state that permits each token only a single write. The post examines dynamic compression, which would allow the model to revisit the past and reorganize its stored information. Ryan Bahlous-Boldi quoted the work, calling dynamic compression a prerequisite for full continual learning and thanking Jyo Pari for leading the project. Alex Zhang also shared the post.

    Combined views

    62.1K

    4 Sources, first seen 41d ago
    Combined views

    62.1K

    4 Sources, first seen 41d ago

    561 likes
    561 likes
    17 comments
    482 saves
    107 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    17 comments
    482 saves
    107 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    4 Sources

    @jyo_pariIn-context continual learning requires models to accumulate experience and reuse it later in the same sequence. But an RNN compresses an ever-growing history into a fixed-size state, where each token gets a single write into memory. We study dynamic compression: letting the model revisit the past and reorganize its state as it discovers what needs to be reused.
    @RyanBoldiContinual learning is soon going to be largely in-context. Our recent work brings forward something that is clearly a prerequisite to full continual learning: dynamically compressing information for future retrieval. Thanks to @jyo_pari for leading this awesome project!
    @a1zhangRT @jyo_pari: In-context continual learning requires models to accumulate experience and reuse it later in the same sequence. But an RNN co…
    @simran_s_aroraCool paper! Multiple passes over the sequence with fixed state models is a powerful axis!