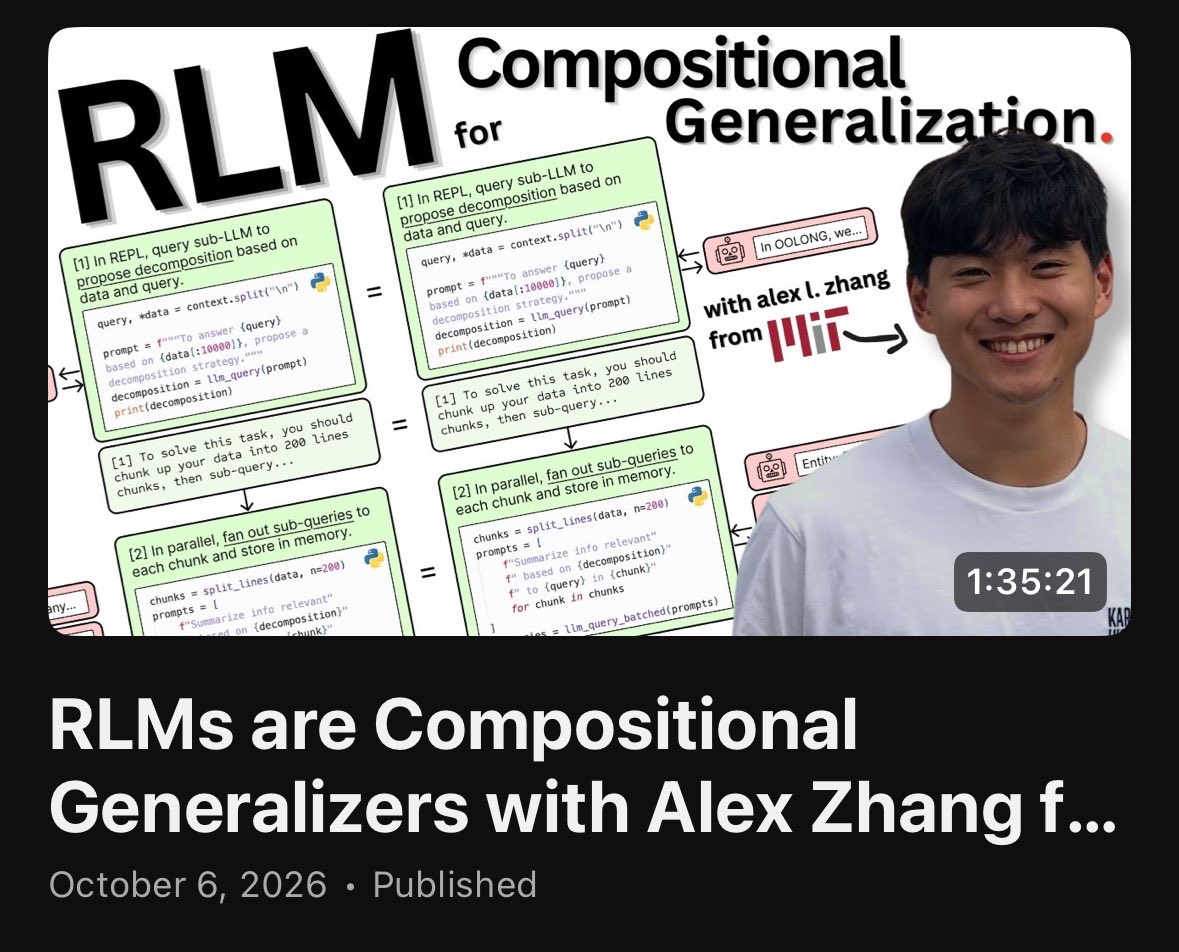
The case for harnesses improving LLM generalization
A post describes a 90-minute chat about compositional generalization, code and what’s still missing.

TLDR
The poster argues that harnesses work well to improve how LLMs generalize. They describe a 90-minute chat covering compositional generalization, having things locally in-distribution, why code is “it” and what’s still missing.
Combined views
64
1 Source, first seen ago