Report
AI-written tests reportedly brought no significant success-rate gain in a DeepSWE evaluation
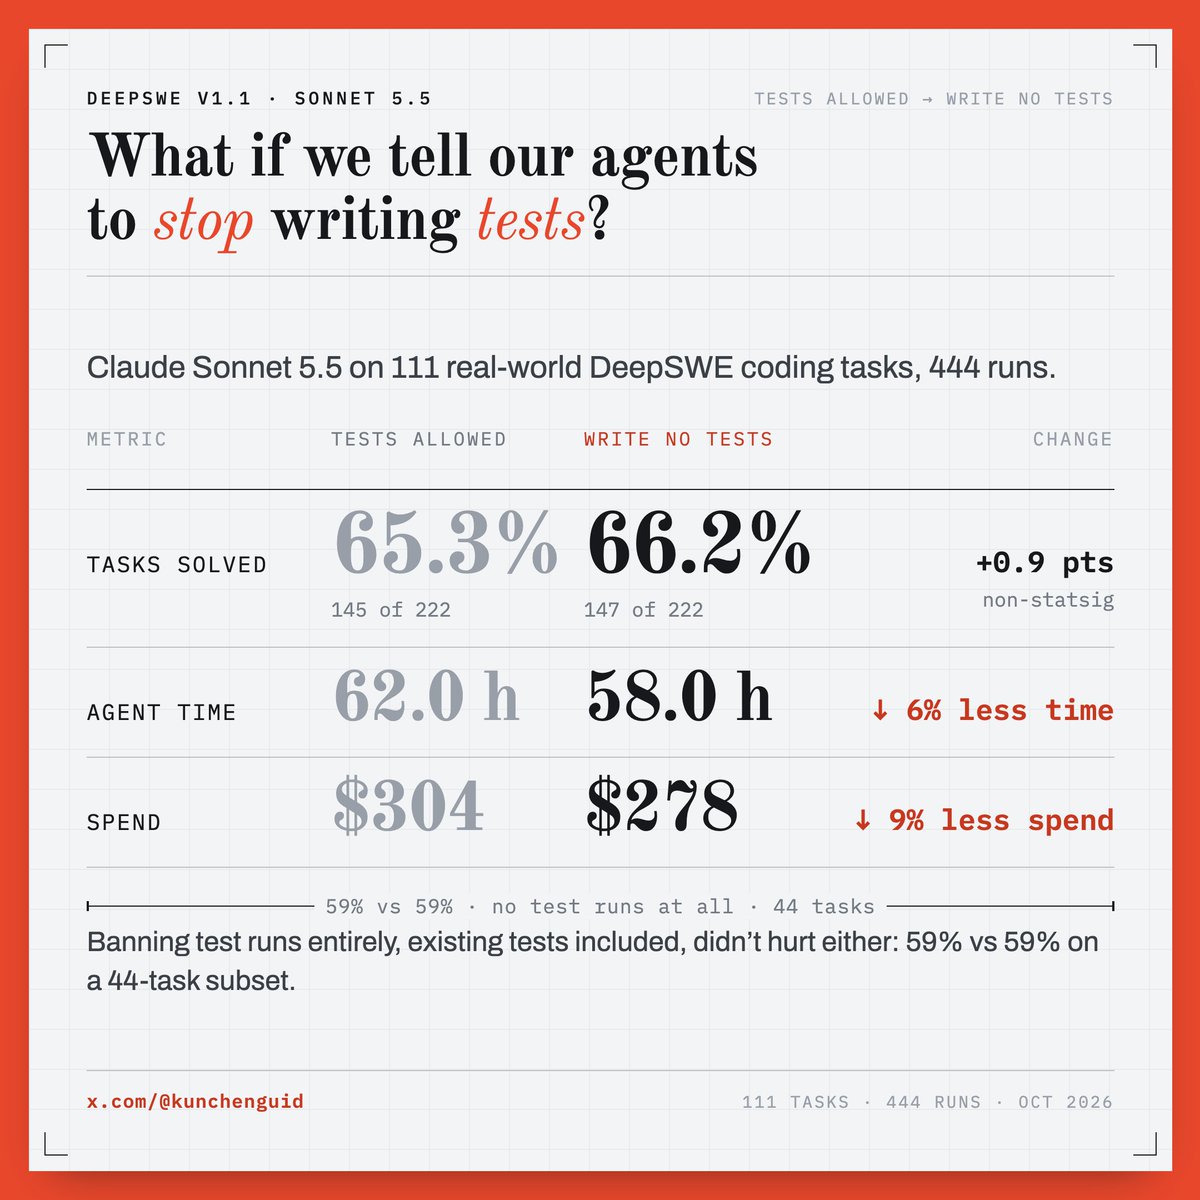
A user reports that barring Sonnet 5.5 High from writing tests significantly reduced time and token use.

TLDR
A user reports that banning Sonnet 5.5 High from writing tests on DeepSWE slightly raised success rates, but not by a statistically significant amount, while significantly reducing time and token use. In the tests-allowed group, 65% of written tests were unit tests and 35% integration tests; neither category improved success. In a 44-task sample, disabling existing tests also left success unchanged. Only 17 end-to-end tests were written, leaving their value unresolved.
Combined views
51
1 Source, first seen ago