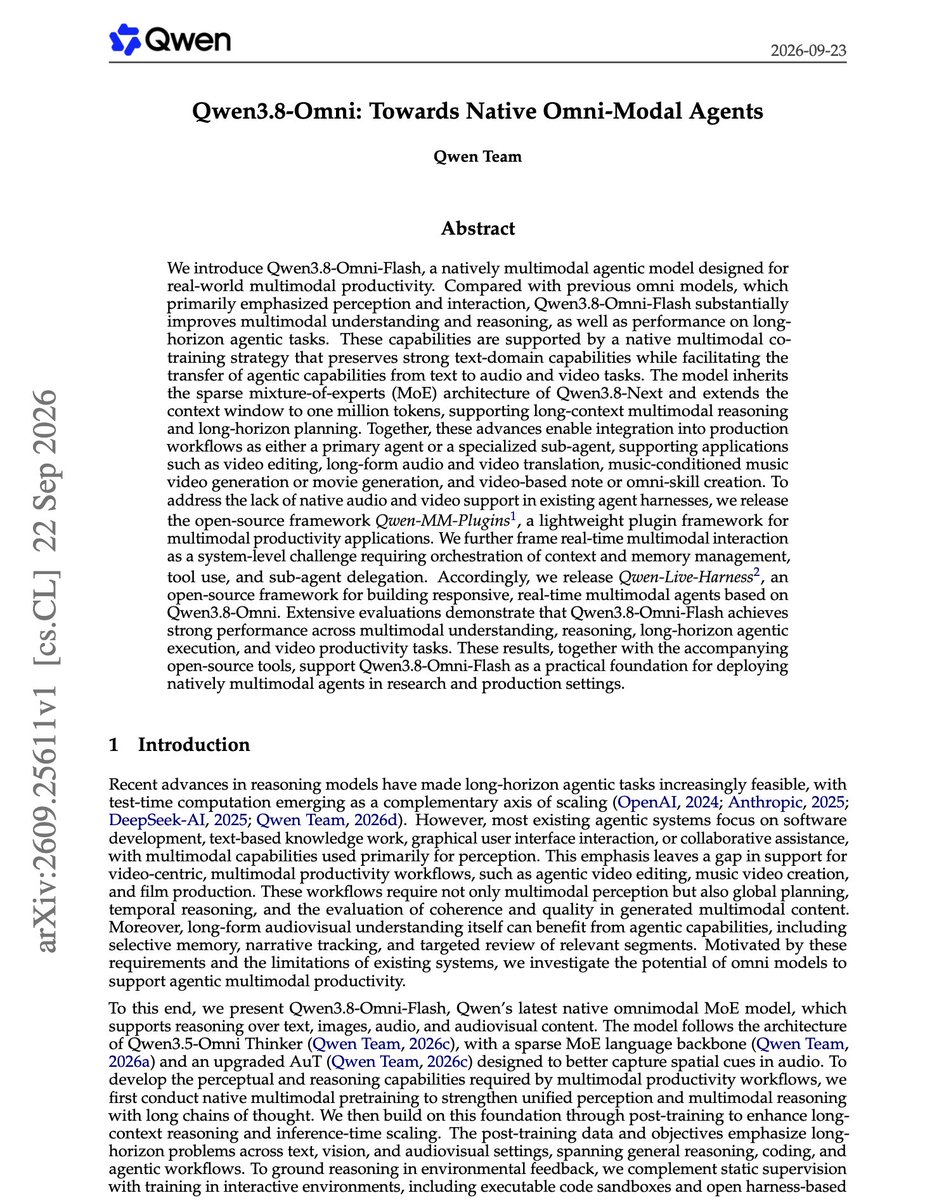
Qwen3.8-Omni-Flash targets long-running agent tasks across text, audio and video
A post summarizing a Qwen Team report describes a model with a one-million-token context window, plus two open-source frameworks for audio and video agents.
TLDR
A post highlighting the Qwen Team’s report describes Qwen3.8-Omni-Flash as a natively multimodal model trained for tasks such as video editing and long-form audio and video translation. It says a co-training approach maintains text performance while extending agent skills to audio and video.
The post also describes two accompanying open-source frameworks: Qwen-MM-Plugins adds audio and video support to existing agent software, while Qwen-Live-Harness handles real-time multimodal interaction, context and memory management, tool use, and delegation to sub-agents.