• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Report

    AC2 proposes partial rollouts to speed up language-model reinforcement learning

    AC2’s proponents say a learned critic scores token chunks, allowing training without finishing every rollout.

    TM
    ZW
    KW
    3 Sources, ,

    TLDR

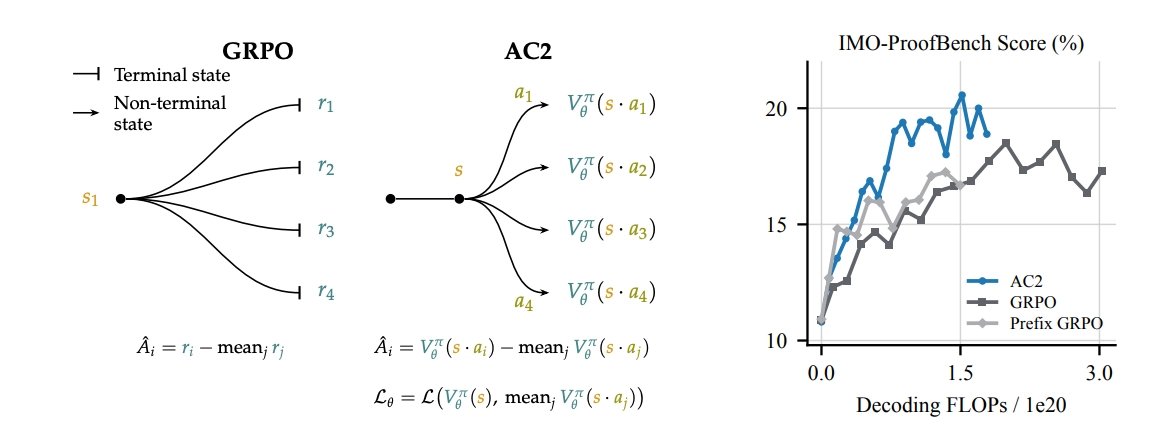
    The proponents of Actor-Critic with Action Chunking (AC2) say a learned critic scores chunks of tokens, allowing reinforcement learning for large language models to use partial rollouts rather than finish every rollout. They claim AC2 trains faster than GRPO.

    Combined views

    19.8K

    3 Sources, first seen 3h ago

    Combined views

    19.8K

    3 Sources, first seen 3h ago

    290 likes
    3h ago
    first seen 3h ago
    290 likes
    16 comments
    207 saves
    67 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    16 comments
    207 saves
    67 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    #15

    Today's Rank

    #15

    3 Sources

    @wen_kaiyueDo you really need to finish every rollout in RL for LLM? Not if you make your critic better—and trust it! We propose Actor-Critic with Action Chunking (AC2): use a learned critic to score chunks of tokens => only need partial rollouts ⇒ train faster than GRPO!3h
    @zhaoran_wangRT @wen_kaiyue: Do you really need to finish every rollout in RL for LLM? Not if you make your critic better—and trust it! We propose Acto…2h
    @tengyumaAlways thought GRPO-style RL can't be optimal. With billions going into self-play & RSI, the underlying RL methods need to be efficient. Very exciting project 🔥: 1. Using critics to supervise policy 2. Exploiting easy resets for LLMs 3. Sharing params between Q & policy2h