• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Report

    AI models may lose their place on long jobs, even within their context windows

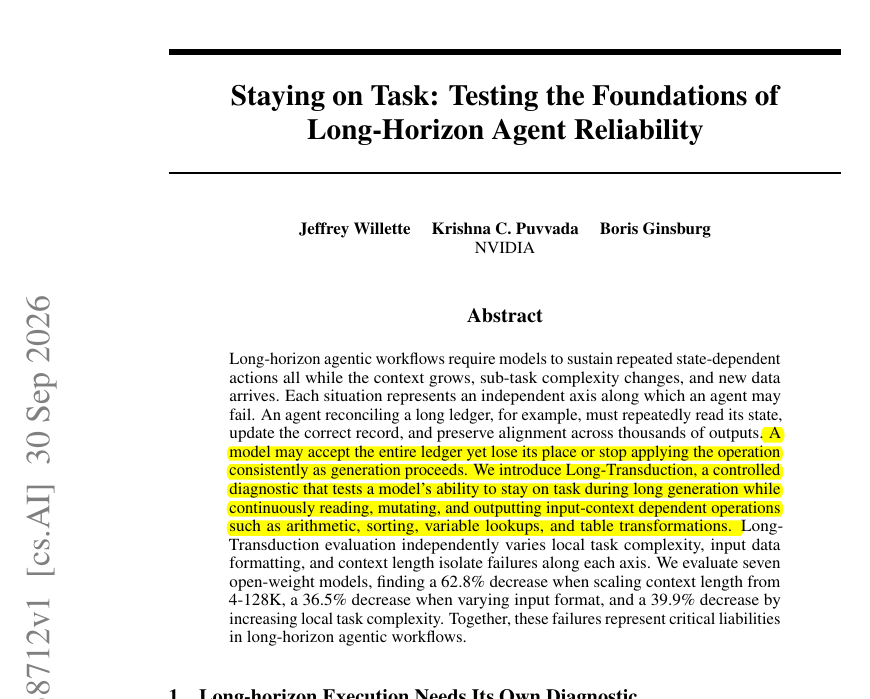
    A post about an Nvidia paper says seven open models had 62.8% lower average accuracy on 128K-token jobs than on 4K-token jobs.

    RP
    1 Source, 2h ago, first seen 2h ago

    TLDR

    A post describing an Nvidia paper says seven open models struggled with long, repetitive tasks such as adding numbers and sorting lists. It reports that average accuracy was 62.8% lower on 128K-token jobs than on 4K-token jobs; even the best model got every item right in only 17.1% of the longest jobs. The post recommends numbering items, working in small batches and checking every output line.

    Combined views

    2.2K

    1 Source, first seen 2h ago

    Combined views

    2.2K

    1 Source, first seen 2h ago

    29 likes
    29 likes
    14 comments
    9 saves
    4 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    14 comments
    9 saves
    4 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    #18

    Today's Rank

    #18

    1 Source

    @rohanpaul_aiNew Nvidia paper: AI models get sloppier as jobs get longer, even inside their context window, so number every item and split big jobs into small chunks. Model size didn't guarantee reliability on long, repetitive jobs Picture an agent updating a huge invoice file line by line. It can read the whole file and still skip a line or update the wrong record. NVIDIA tested 7 open models on simple, repetitive jobs like adding numbers and sorting lists. Average accuracy was 62.8% lower on 128K-token jobs than on 4K-token jobs. Even the best model got every item right in only 17.1% of the longest jobs. The models seemed to understand the task but lost their place, especially when items had no ID numbers. If your agent works through long lists, give every item an ID, process them in small batches, and check every line of output. – arxiv. org/abs/2609.38712 Title: "Staying on Task: Testing the Foundations of Long-Horizon Agent Reliability"2h