AI
Jev reportedly beats LLM judges on speed and cost in a narrow test
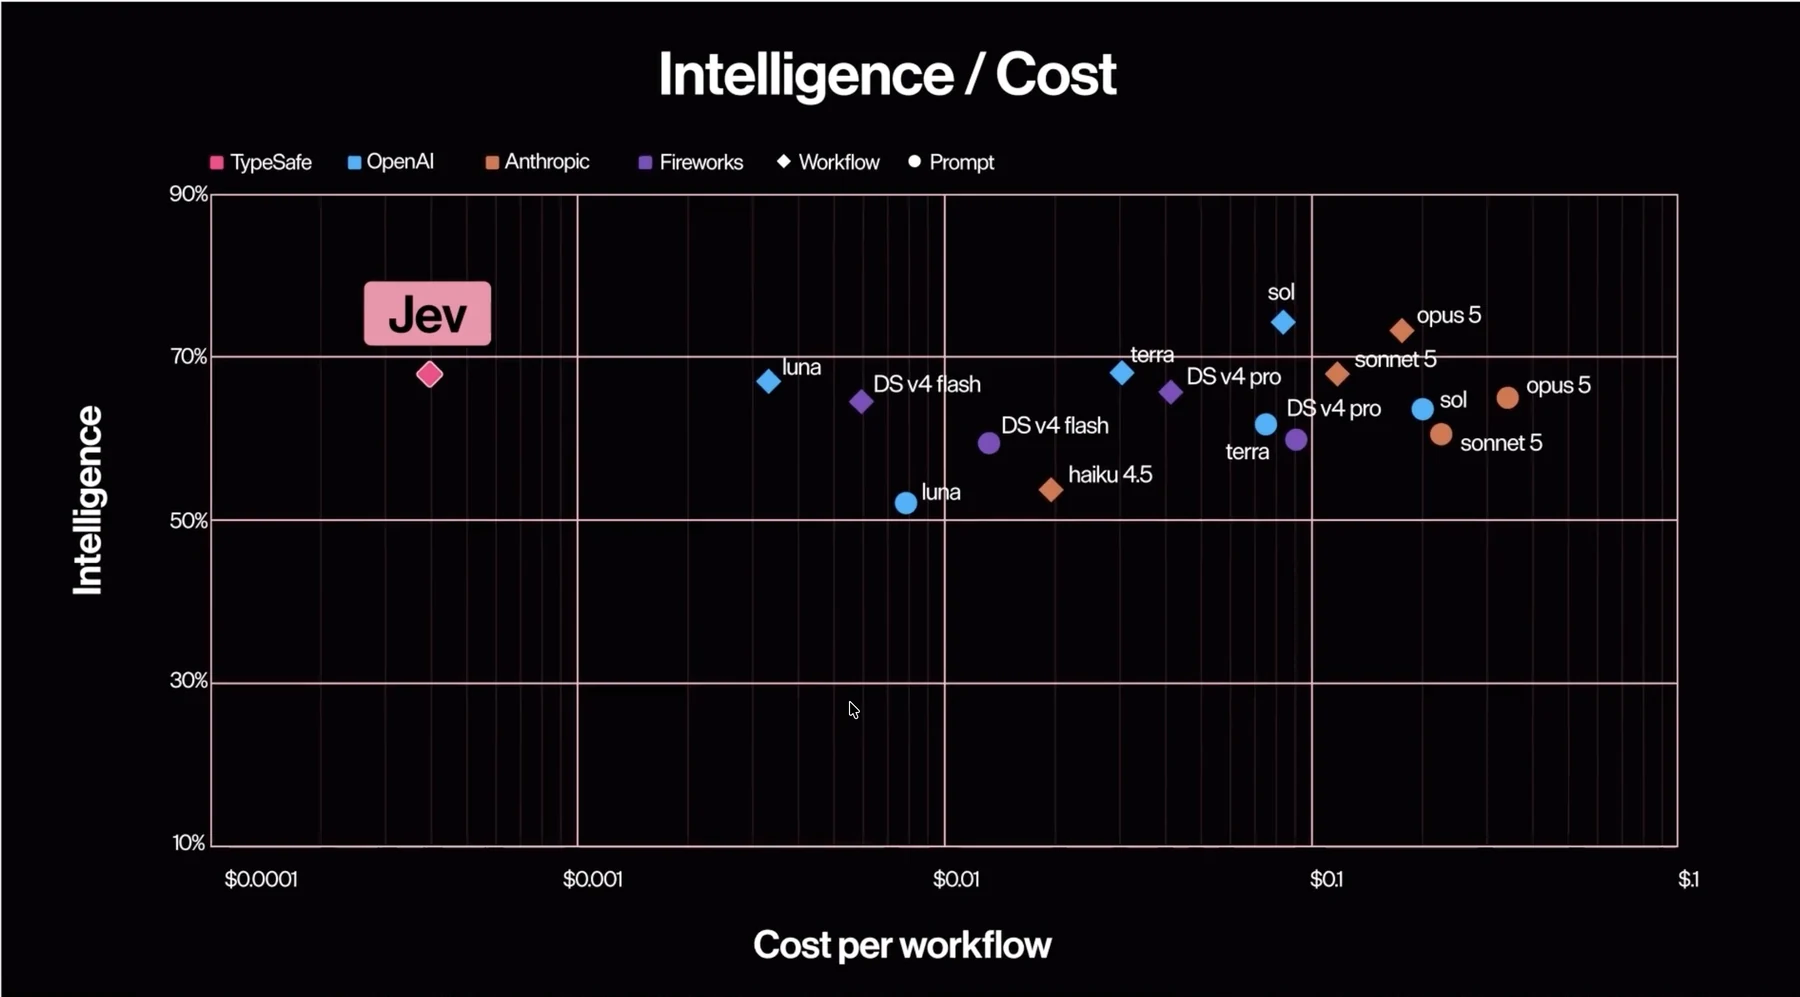
LangChain says TypeSafe AI’s Jev returns structured answers rather than generating text. In its test, Jev’s quality-score variance was 92–913 times lower than that of GPT-5.6 Luna, Terra and Claude Sonnet 4.6.
TLDR
LangChain tested TypeSafe AI’s Jev against LLM judges on accuracy, repeatability, latency and cost. It reports that Jev was the fastest and cheapest evaluator in the comparison, averaging 0.44 seconds and $0.00035 per call. Jev also produced more consistent continuous scores, with substantially lower quality-score variance. LangChain describes the results as promising but early, emphasizing the test’s narrow scope.
Combined views
51.1K
3 Sources, first seen 19h ago
Jev reportedly beats LLM judges on speed and cost in a narrow test
LangChain says TypeSafe AI’s Jev returns structured answers rather than generating text. In its test, Jev’s quality-score variance was 92–913 times lower than that of GPT-5.6 Luna, Terra and Claude Sonnet 4.6.