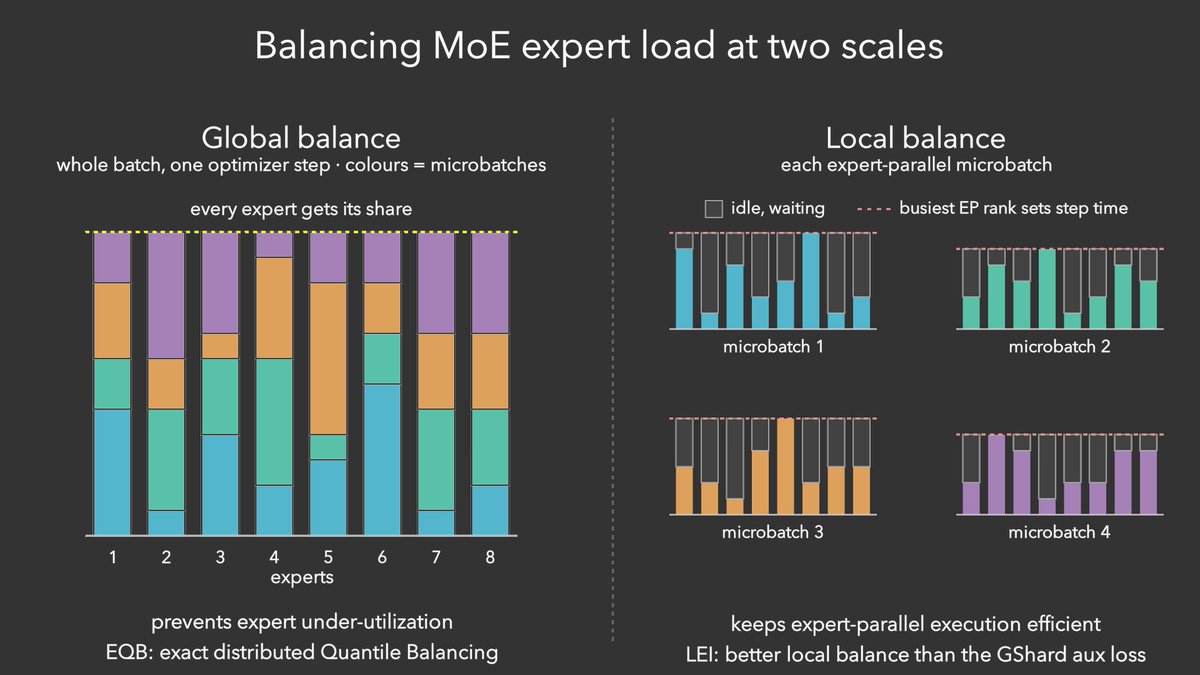
EQB and LEI target global and local load balancing in mixture-of-experts training
A paper co-author reports validation on 7.5B mixture-of-experts models trained on up to 500 billion tokens, addressing expert underuse and parallel-execution efficiency.
TLDR
A paper co-author describes two scales of load balancing in mixture-of-experts training: global balance to prevent experts from being underused, and local balance to keep expert-parallel execution efficient. They say EQB makes distributed global QB exact, improving on the approximate histogram variant used by Kimi K3. They also report that LEI improves local balance over the standard GShard auxiliary loss at comparable quality. The reported validation used 7.5B models trained on up to 500 billion tokens.
Combined views
5.2K
2 Sources, first seen 12h ago