Announcement
SOMA is claimed to achieve lower loss than tested zero-order methods at matched compute and parameter counts
A researcher introducing SOMA says it splits a model into tiny experts trained independently across GPUs, without exchanging gradients, activations or optimizer state during training.
TLDR
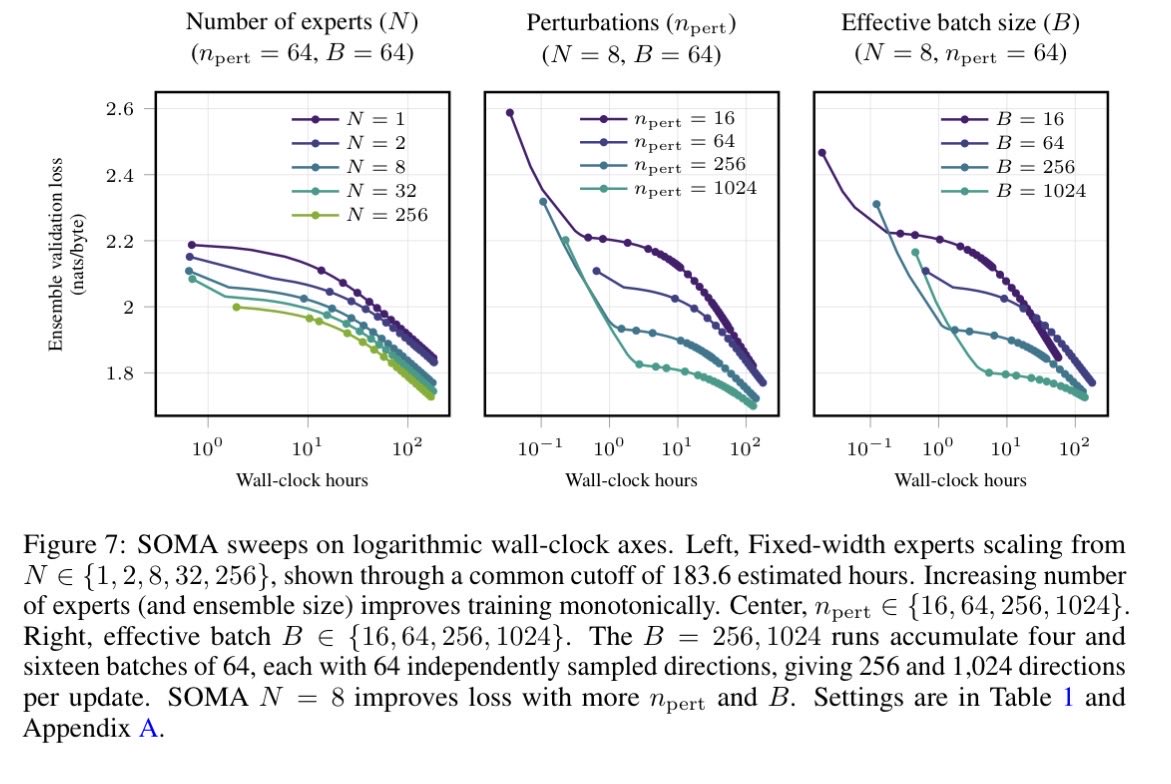
A researcher introducing SOMA says the architecture is designed to cap the gradient variance that makes zero-order optimization harder as models grow. They report lower loss than all monolithic zero-order methods they tested at equal compute and parameter counts. They also say selecting fewer experts at inference can reduce compute, trading off accuracy without retraining.
Combined views
20K
2 Sources, first seen 13h ago