Report
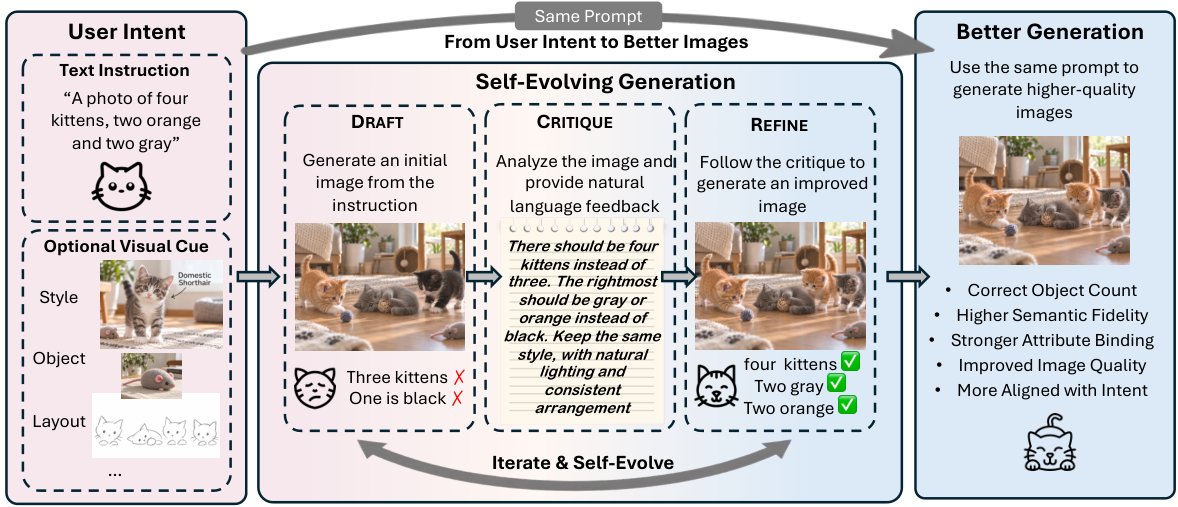
UniEvo-VL aims to improve image generation through a model’s own feedback
HuggingPapers describes one multimodal model acting as both teacher and student, learning without external supervision.
TLDR
HuggingPapers describes UniEvo-VL as a self-evolving framework that uses a single multimodal model as both teacher and student. It says the model learns from its own constructive feedback to boost image generation without external supervision.
Combined views
4K
2 Sources, first seen 5h ago
19 likes