• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Neuro-Symbolic Computer Use aims to give AI agents reusable, repairable skills

    Its introducer says stable knowledge becomes executable code, while perception and uncertain decisions remain neural.

    XE
    AL
    3 Sources, ,

    TLDR

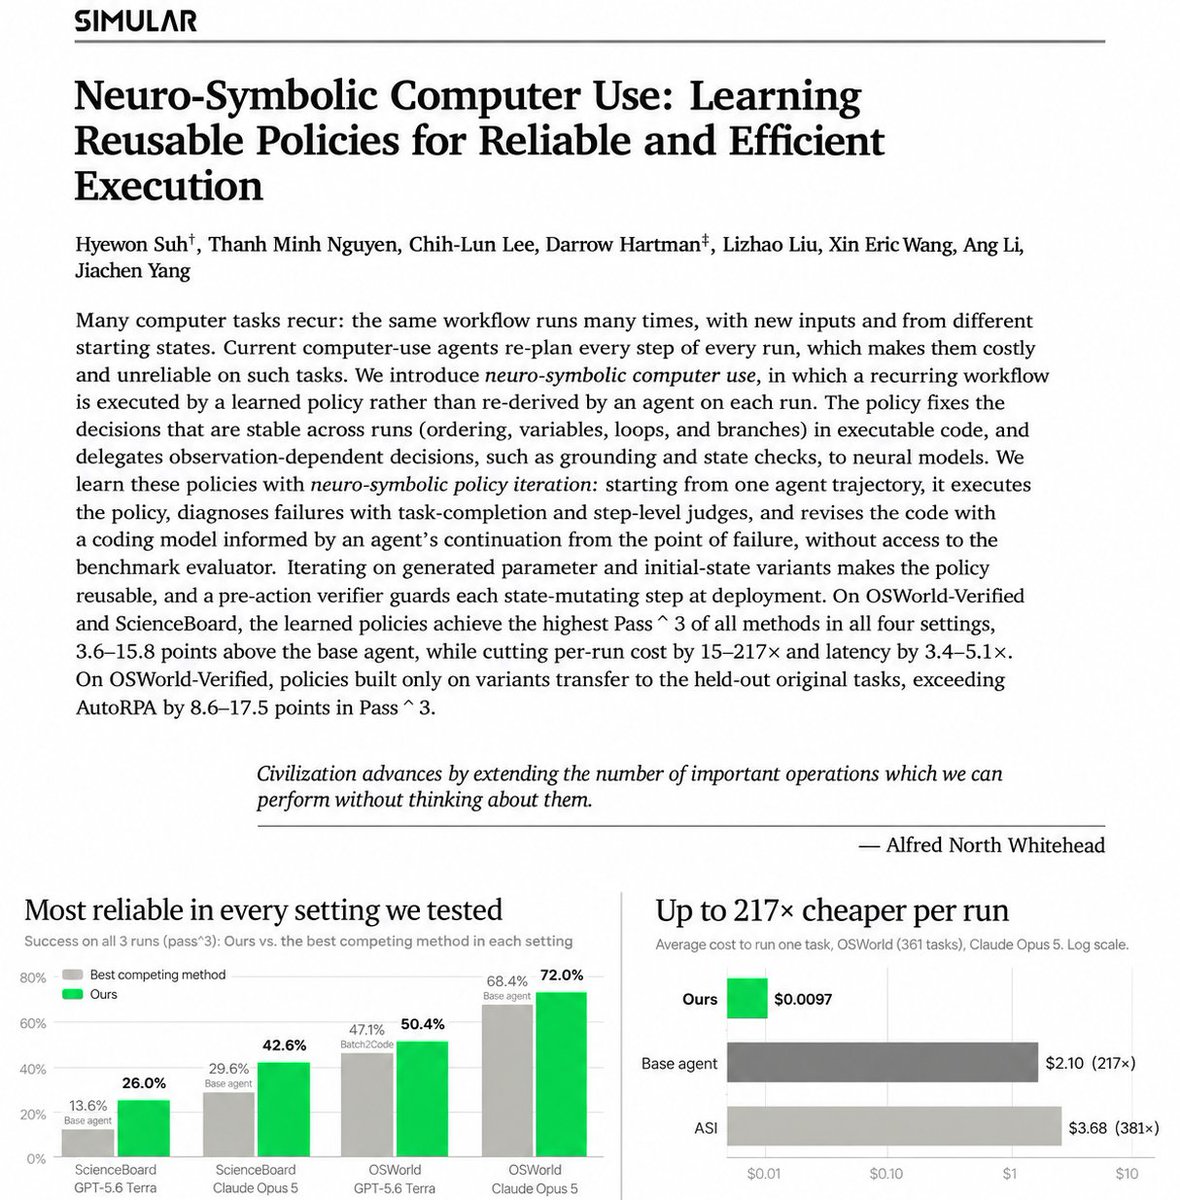
    The author introduces Neuro-Symbolic Computer Use as a way for agents to turn experience into policies they can reuse and repair after failures. They claim a state-of-the-art pass³ success rate across all four settings, improving by 3.6–15.8 points, plus up to 217× lower execution cost and up to 5.1× lower latency.

    Combined views

    2.2K

    3 Sources, first seen 3h ago
    Combined views

    2.2K

    3 Sources, first seen 3h ago

    26 likes
    3h ago
    first seen 3h ago
    26 likes
    11 comments
    16 saves
    5 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    11 comments
    16 saves
    5 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    3 Sources

    @xwang_lkMost AI agents today are disposable reasoners. They solve a task once, then start from scratch the next time. And when a learned workflow breaks, they often fall back to reasoning from scratch again. I think agents should work very differently: 𝐥𝐞𝐚𝐫𝐧 → 𝐫𝐞𝐮𝐬𝐞 → 𝐟𝐚𝐢𝐥 → 𝐫𝐞𝐩𝐚𝐢𝐫 → 𝐢𝐦𝐩𝐫𝐨𝐯𝐞 Introducing 𝐍𝐞𝐮𝐫𝐨-𝐒𝐲𝐦𝐛𝐨𝐥𝐢𝐜 𝐂𝐨𝐦𝐩𝐮𝐭𝐞𝐫 𝐔𝐬𝐞, where agents turn execution experience into reusable, continually improving policies. Instead of repeatedly paying a frontier model to re-plan every action, the agent distills experience into a neuro-symbolic program: stable knowledge becomes executable code, while perception and uncertain decisions remain neural. More importantly, these policies are not static. When execution fails, the agent diagnoses what went wrong, reasons about what should have happened, and repairs the policy for future runs. In that sense, the agent becomes 𝐬𝐞𝐥𝐟-𝐡𝐞𝐚𝐥𝐢𝐧𝐠: failures are not just errors to recover from, but opportunities to improve the underlying skill. As the agent encounters new parameters, states, and edge cases, the same policy can keep evolving. The policy itself becomes a form of 𝐚𝐜𝐜𝐮𝐦𝐮𝐥𝐚𝐭𝐞𝐝 𝐨𝐩𝐞𝐫𝐚𝐭𝐢𝐨𝐧𝐚𝐥 𝐦𝐞𝐦𝐨𝐫𝐲. To me, this points toward an important direction for continual learning in agents. Continual learning doesn’t have to mean constantly updating billions of model weights. It can also mean 𝐜𝐨𝐧𝐭𝐢𝐧𝐮𝐚𝐥𝐥𝐲 𝐛𝐮𝐢𝐥𝐝𝐢𝐧𝐠, 𝐫𝐞𝐮𝐬𝐢𝐧𝐠, 𝐫𝐞𝐩𝐚𝐢𝐫𝐢𝐧𝐠, 𝐚𝐧𝐝 𝐫𝐞𝐟𝐢𝐧𝐢𝐧𝐠 𝐞𝐱𝐞𝐜𝐮𝐭𝐚𝐛𝐥𝐞 𝐬𝐤𝐢𝐥𝐥𝐬 𝐟𝐫𝐨𝐦 𝐞𝐱𝐩𝐞𝐫𝐢𝐞𝐧𝐜𝐞. The results: - 𝐒𝐎𝐓𝐀 𝐩𝐚𝐬𝐬^3 𝐬𝐮𝐜𝐜𝐞𝐬𝐬 𝐫𝐚𝐭𝐞 across all four settings, improving by 3.6–15.8 𝐩𝐨𝐢𝐧𝐭𝐬 - Up to 217× 𝐥𝐨𝐰𝐞𝐫 𝐞𝐱𝐞𝐜𝐮𝐭𝐢𝐨𝐧 𝐜𝐨𝐬𝐭 - Up tp 5.1× 𝐥𝐨𝐰𝐞𝐫 𝐥𝐚𝐭𝐞𝐧𝐜𝐲 Long term, useful agents shouldn’t just be able to reason. They should 𝐫𝐞𝐦𝐞𝐦𝐛𝐞𝐫 𝐰𝐡𝐚𝐭 𝐭𝐡𝐞𝐲 𝐥𝐞𝐚𝐫𝐧𝐞𝐝, 𝐫𝐞𝐮𝐬𝐞 𝐰𝐡𝐚𝐭 𝐚𝐥𝐫𝐞𝐚𝐝𝐲 𝐰𝐨𝐫𝐤𝐬, 𝐫𝐞𝐩𝐚𝐢𝐫 𝐰𝐡𝐚𝐭 𝐛𝐫𝐞𝐚𝐤𝐬, 𝐚𝐧𝐝 𝐢𝐧𝐜𝐫𝐞𝐚𝐬𝐢𝐧𝐠𝐥𝐲 𝐤𝐧𝐨𝐰 𝐰𝐡𝐚𝐭 𝐭𝐡𝐞𝐲 𝐧𝐨 𝐥𝐨𝐧𝐠𝐞𝐫 𝐧𝐞𝐞𝐝 𝐭𝐨 𝐫𝐞𝐚𝐬𝐨𝐧 𝐚𝐛𝐨𝐮𝐭. Very proud of the team for pushing toward this vision.
    @angli_aiWe just beat the state of the art in computer use and reduced the cost by 100x. And released the API. You are welcome.