Announcement
LeanLean is a new benchmark for compressing Lean codebases
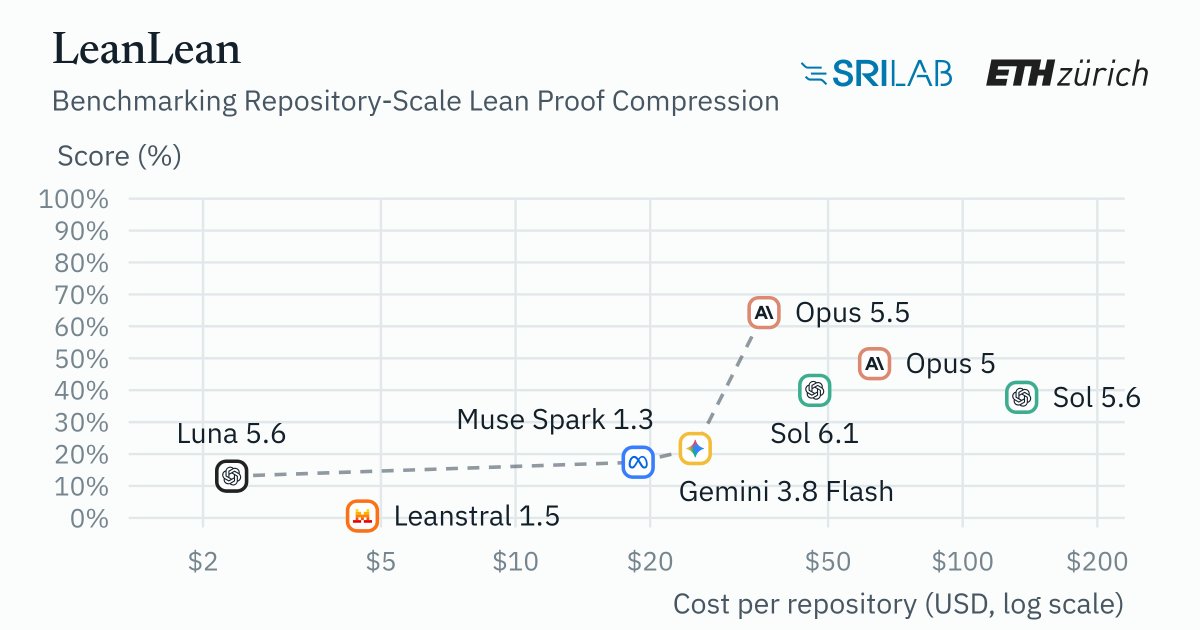
Its creators say Opus 5.5 leads the leaderboard with a 64.3% score, versus 39.9% for GPT 6.1 Sol.


TLDR
LeanLean’s creators introduced the benchmark as LLM-written proofs grow longer, citing what they describe as Claude’s 13-million-line Lean proof of Fermat’s Last Theorem. They report a 64.3% leaderboard score for Opus 5.5, compared with 39.9% for GPT 6.1 Sol.
Combined views
3.1K
2 Sources, first seen ago