Reaction
The case for benchmarking the AI research process, not just its score
A user says Fable pushes bigger ideas, while Astra recommends a pilot and careful evidence checks for the same task.


TLDR
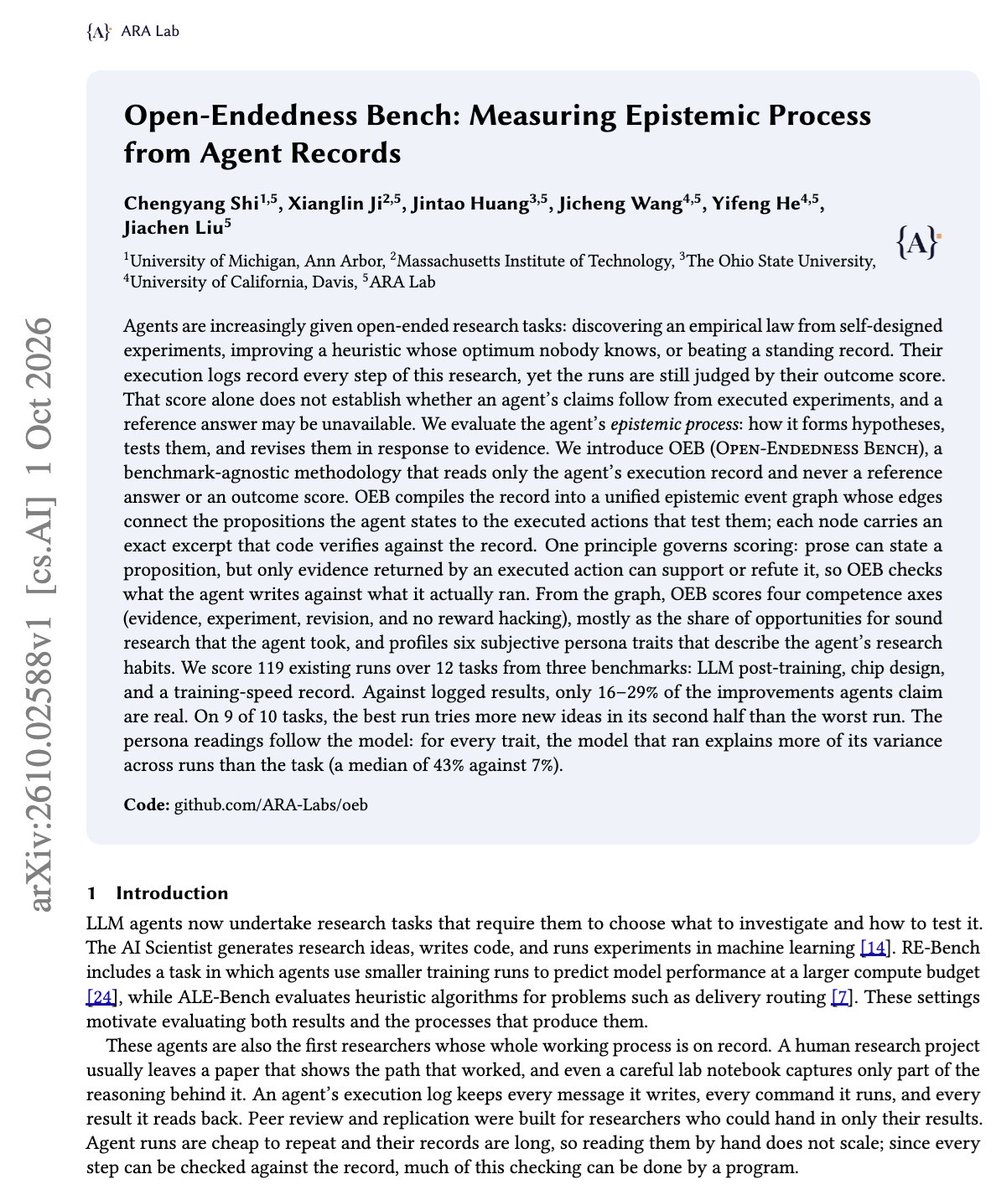
A user argues that benchmark leaderboards reduce scientific exploration to a single number, missing differences in how AI systems approach research. They contrast Fable’s push to try bigger things with Astra’s advice to run a pilot and validate evidence, and say research logs could make it possible to benchmark the process itself.
Combined views
5.2K
2 Sources, first seen ago