Report
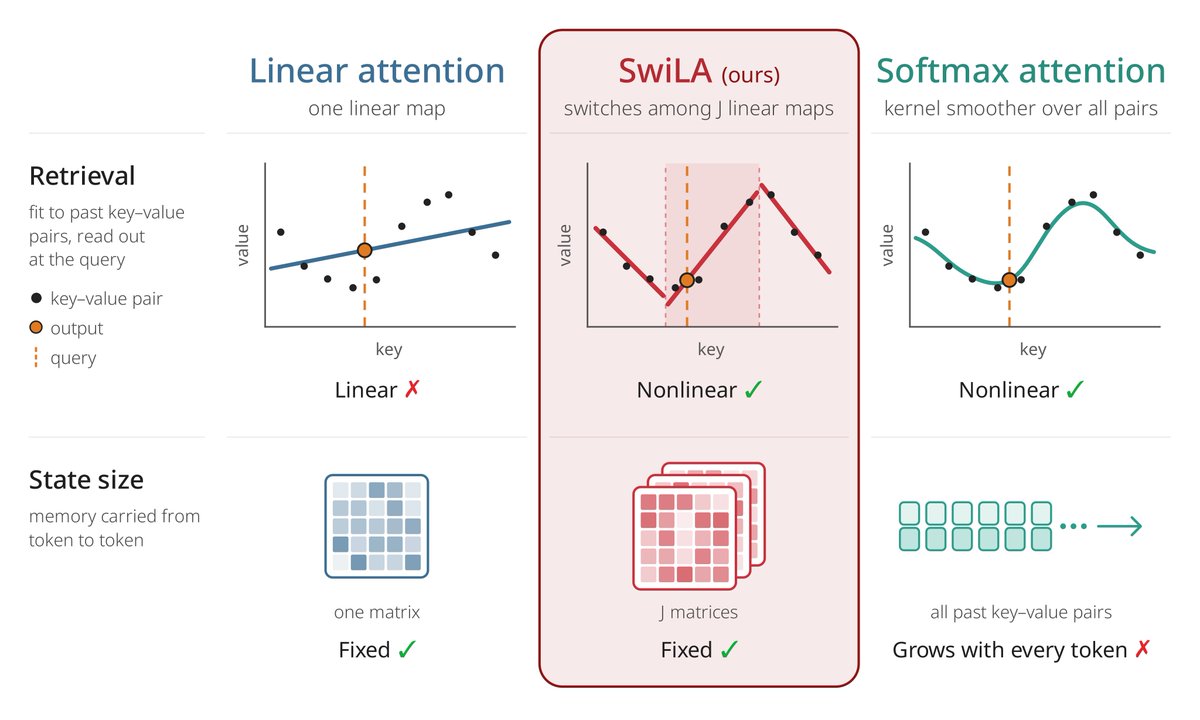
Switching Linear Attention aims to pair expressiveness with a fixed-size state
The COLM 2026 paper’s authors say SwiLA switches among multiple linear maps to combine the strengths of two attention methods.

TLDR
The researchers behind Switching Linear Attention (SwiLA) say it addresses a trade-off: softmax attention is expressive, but its KV cache grows with sequence length; linear attention keeps a fixed-size state, but is less expressive. They say SwiLA switches among multiple linear maps to get the best of both approaches.
Combined views
4
1 Source, first seen ago