• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

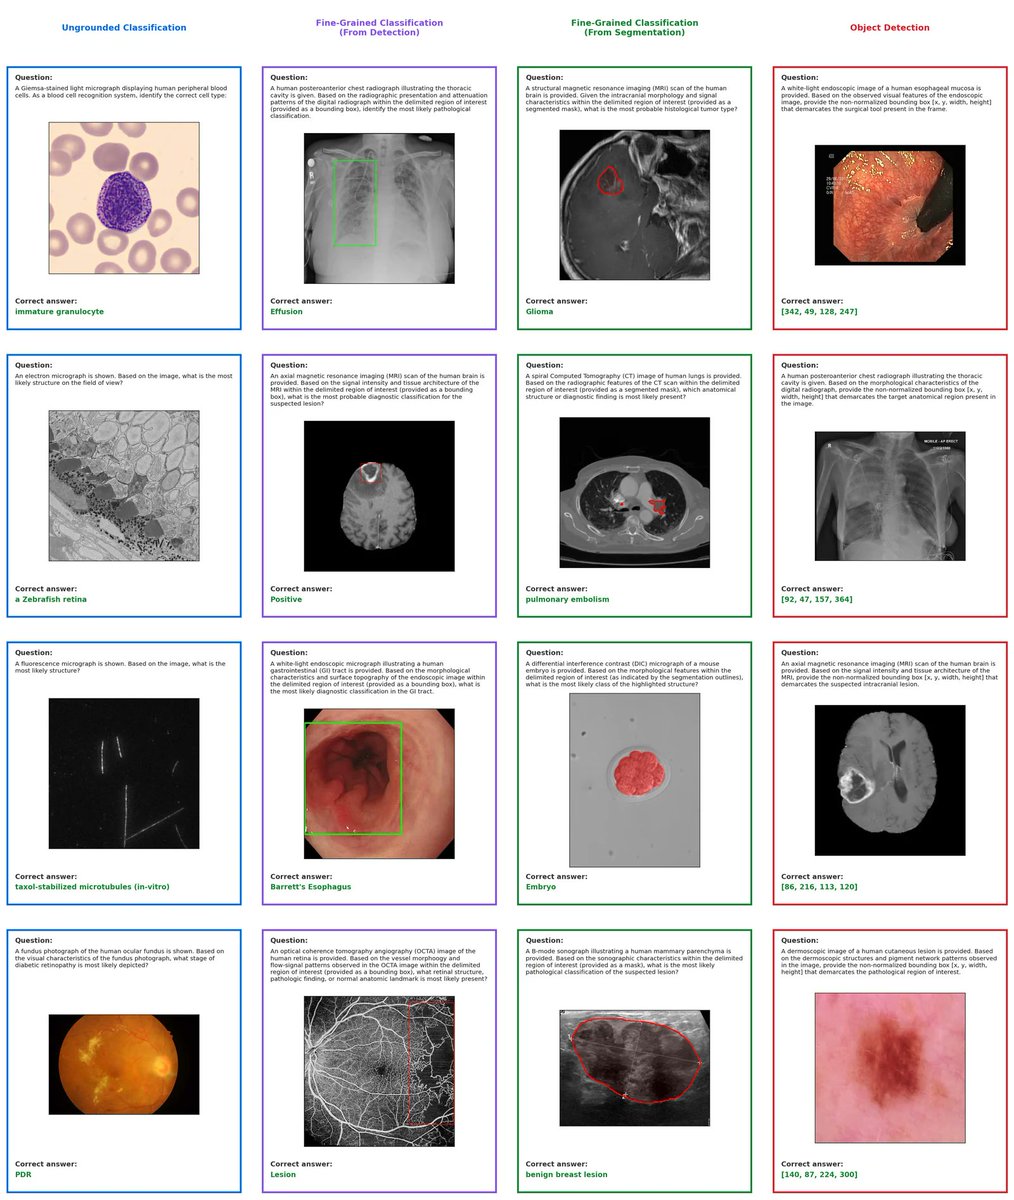
    MMBU Challenge aims to test whether AI understands biomedical images

    A collaborator says models can answer medical questions correctly while missing basic visual context, such as the imaging modality, body part, specimen or stain.

    TM
    LA
    4 Sources, ,

    TLDR

    A collaborator announced the MMBU Challenge, organized by Stanford MARVL, to test whether models can recognize and locate what’s in biomedical images—not just give the right answer. The September 30, 2026, announcement listed three tracks, $100K-plus in compute and prizes, and an October 1–December 31 schedule. Registration was set to close September 30.

    Combined views

    30.4K

    4 Sources, first seen 8h ago
    Combined views

    30.4K

    4 Sources, first seen 8h ago

    120 likes
    8h ago
    first seen 8h ago
    120 likes
    13 comments
    67 saves
    25 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    13 comments
    67 saves
    25 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    4 Sources

    @LiorOnAIIt's time to solve one of the biggest challenges in vision-language models. Today's multimodal models can look at a biomedical image and give a convincing, sometimes correct, answer without actually understanding what they're seeing. A model might answer the medical question correctly while failing to identify basic visual context like the imaging modality, body part, specimen, or stain. So, I'm teaming up with Stanford to solve this problem. You should too. The MMBU Challenge tests whether models can actually recognize, localize, and understand what is in biomedical images, not just arrive at the right answer. 🏆 3 tracks 💻 $100K+ in compute and prizes 📅 Oct 1 to Dec 31 ⏰ Registration closes today
    @iScienceLuvrFrontier VLMs perception of biomedical images still struggle significantly, and is one of the primary bottlenecks in frontier medical capabilities. The MMBU challenge aims to address this, and it is officially about to start! 3 tracks. $100K+ in compute and prizes. Oct 1–Dec 31. Highly recommend checking it out, last chance to sign up! Register: https://luma.com/28k1tyd3 Link: https://akiranishii.github.io/mmbu-challenge/