Report
A method for discovering language-model response styles without supervision and controlling them
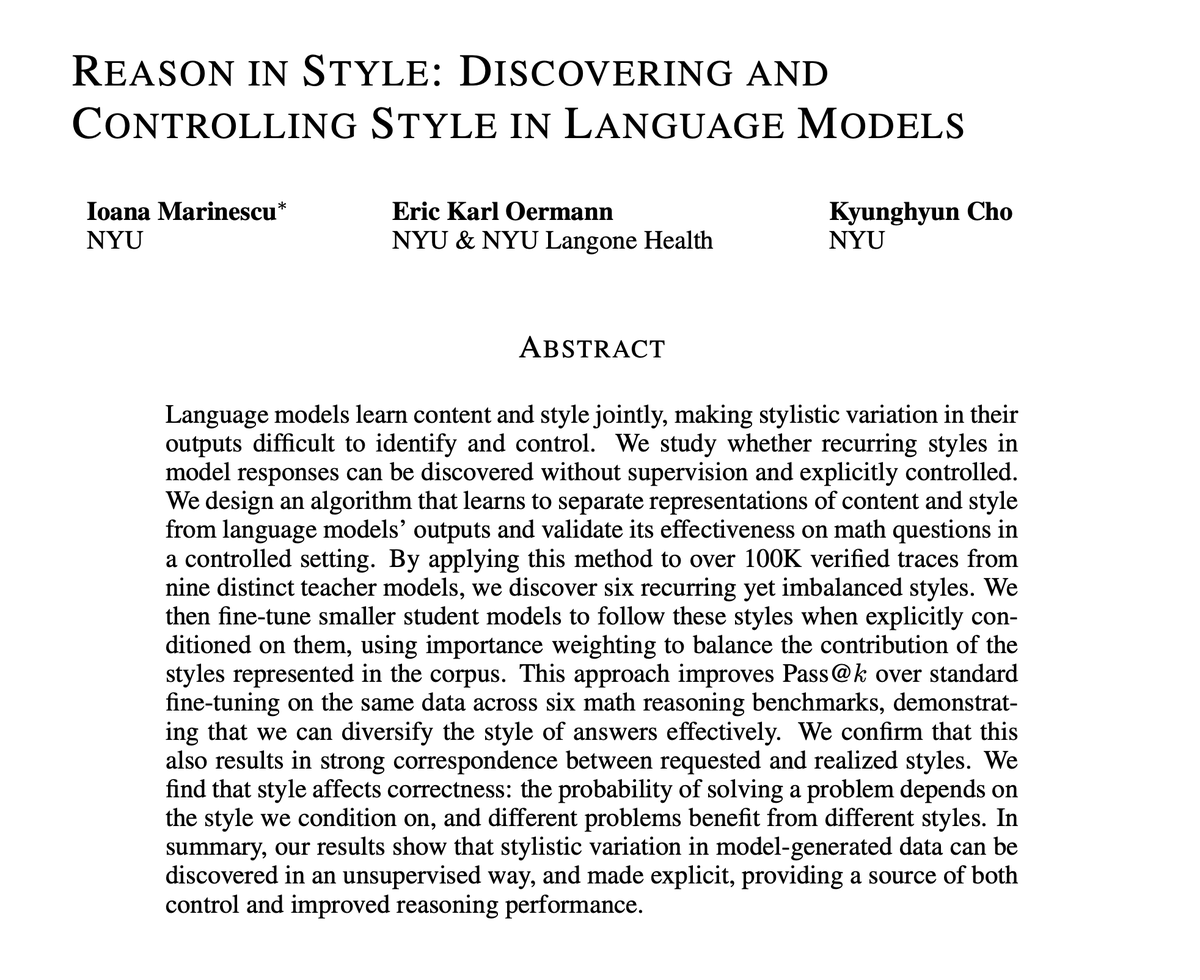
In a preprint, researchers report finding six recurring styles in over 100,000 verified traces from nine teacher models.

TLDR
The preprint’s authors say their method separates content from style in language-model responses. They found six recurring, unevenly represented styles in over 100,000 verified traces from nine teacher models. They report that training smaller models to follow those styles improved Pass@k over standard fine-tuning on the same data across six math-reasoning benchmarks. They also found that the requested style affected the probability of solving a problem.
Combined views
1 Source, first seen ago