• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    A 1991 paper's claimed role in three techniques used by modern language models

    Jürgen Schmidhuber says his paper introduced deep-net pre-training, positional encoding and neural-network distillation.

    Jürgen SchmidhuberJS
    2 Sources, 2h ago, first seen 2h ago

    TLDR

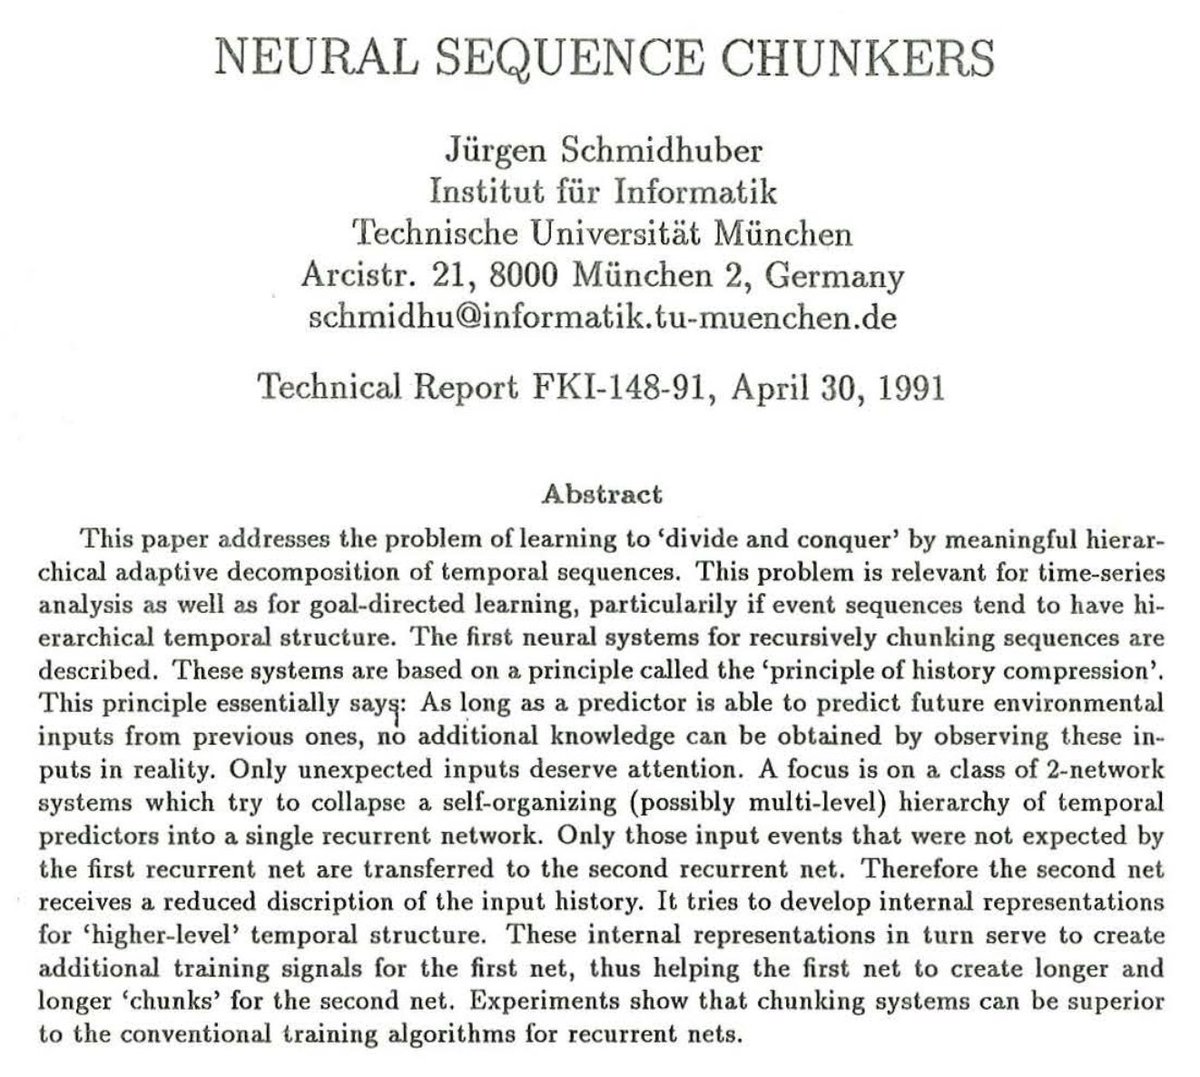
    Jürgen Schmidhuber says his 1991 paper, “Neural sequence chunkers,” introduced three techniques he considers essential to modern large language models: pre-training for deep neural networks, positional encoding and distilling knowledge from one neural network to another. His overview describes networks trained to predict their next input, passing unexpected inputs to higher levels.

    Combined views

    10K

    2 Sources, first seen 2h ago

    Combined views

    10K

    2 Sources, first seen 2h ago

    152 likes
    152 likes
    11 comments
    42 saves
    20 reposts
    11 comments
    42 saves
    20 reposts
    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    Jürgen Schmidhuber@SchmidhuberAIMy 1991 paper [1] introduced 3 techniques that have become essential for modern large language models: ★ Pre-training for deep neural nets - the P in ChatGPT ★ Positional encoding (Sec. 5.1) ★ Distilling the knowledge in a neural net (Sec. 3.2.2 & 4) [1] Neural sequence chunkers. TR FKI-148-91, TUM, April 1991 https://people.idsia.ch/~juergen/FKI-148-91ocr.pdf Journal publication: Learning complex, extended sequences using the principle of history compression. Neural Computation, 4(2):234-242, 1992. See also the overview https://people.idsia.ch/~juergen/very-deep-learning-1991.html2h