• Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    AI

    LLMs may encode reasoning operations separately from whether they’re correct

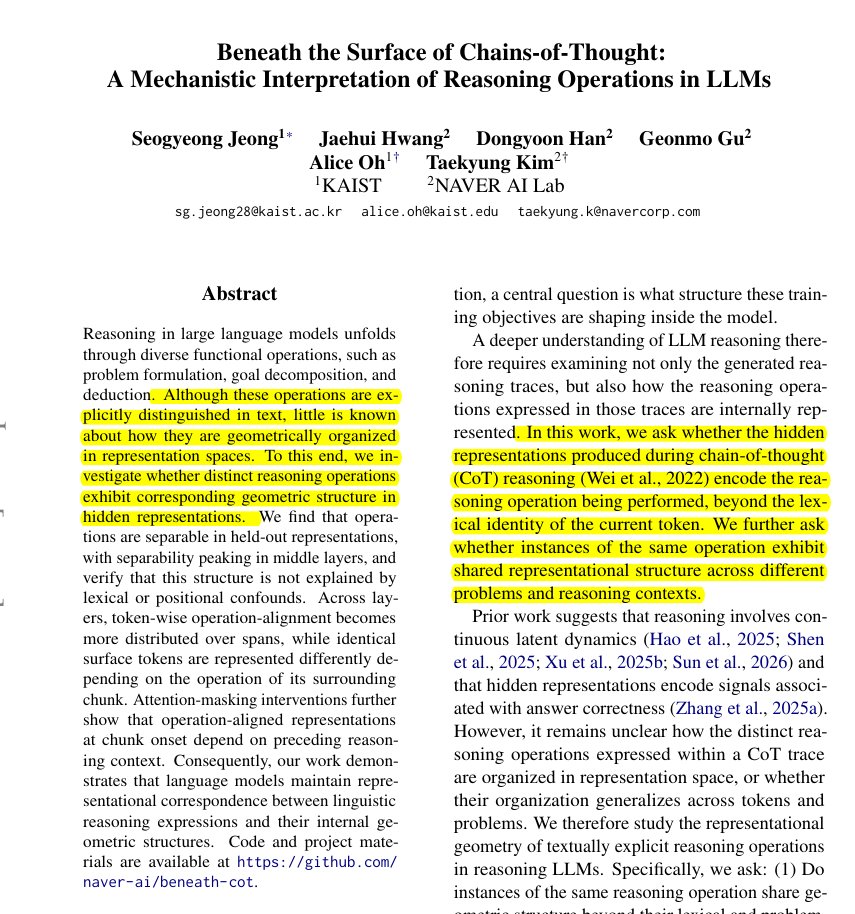
    A post summarizing a paper says eight reasoning operations produced distinct internal patterns, clearest in the model’s middle layers—even when a calculation or deduction was wrong.

    1 Source, 20d ago, first seen 20d ago

    TLDR

    According to a post summarizing the paper, researchers tracked eight common reasoning moves, including extracting facts, recall, deduction, algebra and calculation. Even the same token looked different internally depending on its reasoning role. Blocking access to the previous 30 tokens weakened the signal for the next operation. The post highlights a key distinction: an incorrect calculation or deduction could still carry the correct operation signature, suggesting that what reasoning a model attempts and whether it succeeds may be separable internally.

    Combined views

    —

    1 Source, first seen 20d ago

    — likes— comments— saves— reposts

    Combined views

    —

    1 Source, first seen 20d ago

    — likes— comments— saves— reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    1 Source

    Rohan Paul@rohanpaul_aiThe paper finds that LLM reasoning has an internal structure beyond the words being generated, opening a possible route to monitoring reasoning from inside the model. What an LLM is trying to do and whether it is doing it correctly appear to be separable internally. The researchers tracked 8 common moves, including extracting facts, decomposition, recall, deduction, algebra, and calculation. Each move produced a distinct internal pattern, and those patterns were clearest around the middle layers. Even the exact same token looked different inside the model depending on the reasoning job it was doing. Context also shaped these states. When access to the previous 30 tokens was blocked, the signal for the next reasoning operation weakened. Most importantly, a wrong calculation or deduction could still carry the correct operation signature. The model can represent what kind of reasoning it is attempting without necessarily getting that reasoning right. – arxiv. org/abs/2609.04753 Title: "Beneath the Surface of Chains-of-Thought: A Mechanistic Interpretation of Reasoning Operations in LLMs"20d
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI

    1 Source

    Rohan Paul@rohanpaul_aiThe paper finds that LLM reasoning has an internal structure beyond the words being generated, opening a possible route to monitoring reasoning from inside the model. What an LLM is trying to do and whether it is doing it correctly appear to be separable internally. The researchers tracked 8 common moves, including extracting facts, decomposition, recall, deduction, algebra, and calculation. Each move produced a distinct internal pattern, and those patterns were clearest around the middle layers. Even the exact same token looked different inside the model depending on the reasoning job it was doing. Context also shaped these states. When access to the previous 30 tokens was blocked, the signal for the next reasoning operation weakened. Most importantly, a wrong calculation or deduction could still carry the correct operation signature. The model can represent what kind of reasoning it is attempting without necessarily getting that reasoning right. – arxiv. org/abs/2609.04753 Title: "Beneath the Surface of Chains-of-Thought: A Mechanistic Interpretation of Reasoning Operations in LLMs"20d
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet