Report
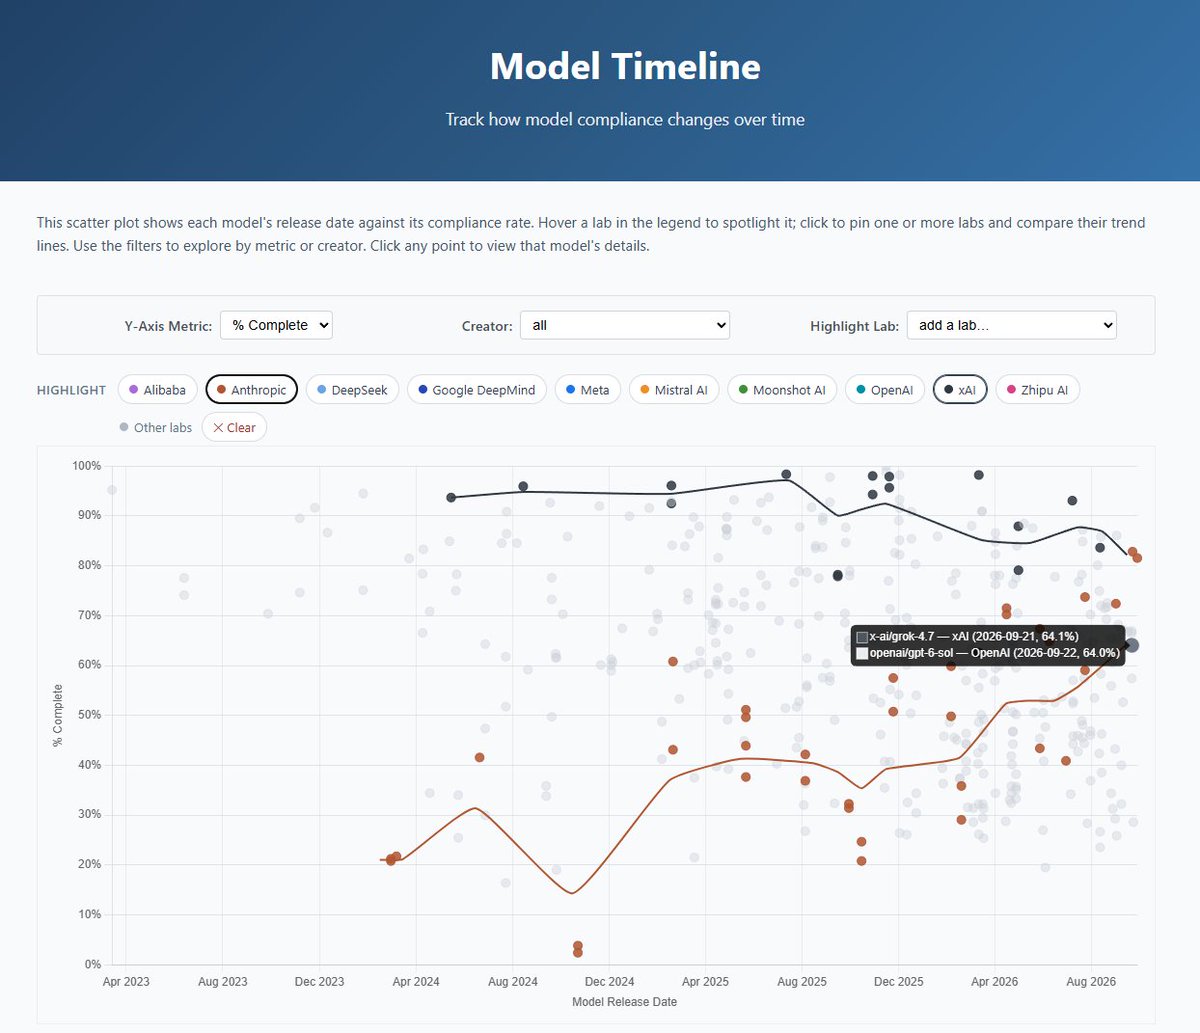
Reported SpeechMap scores put Anthropic's 5.5 models at a company high and Grok 4.7 at an xAI low
A post says Grok 4.7 scored 19 percentage points below Grok 4.6 and 18 points below Opus 5.5 on SpeechMap.ai, which tracks whether models help compose diverse political speech.
TLDR
A user says Anthropic's latest 5.5 models are its highest-scoring yet on SpeechMap.ai, while Grok 4.7 has xAI's lowest score yet. The post puts Grok 4.7 19 percentage points below Grok 4.6 and 18 points below Opus 5.5.
Combined views
873
1 Source, first seen 2h ago
31 likes