• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Could looped language models match Transformers with 3× fewer parameters and a 3× smaller KV cache?

    A post introducing “Rethinking at Fixed Points” proposes fixed-point shortcuts for training and inference.

    CL
    BH
    2 Sources, ,

    TLDR

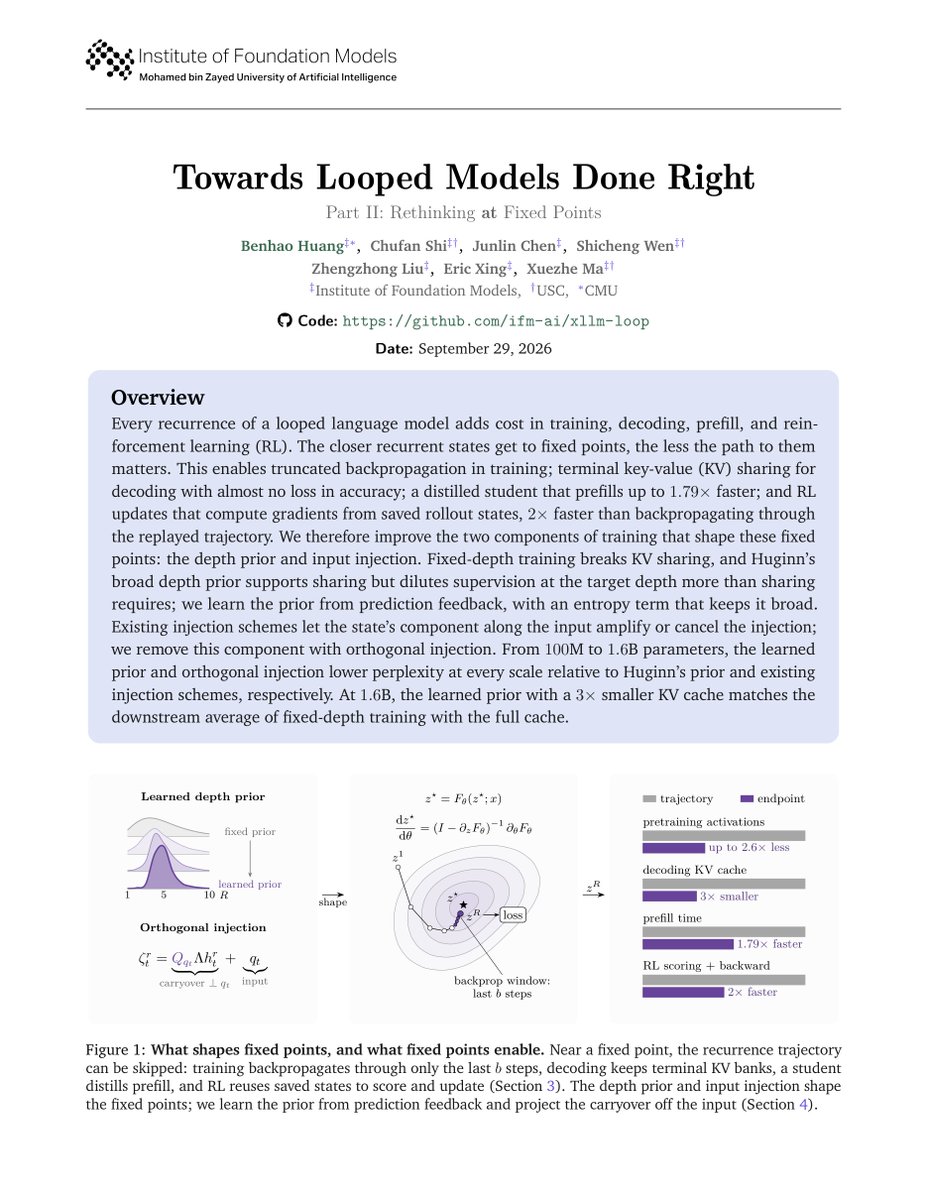
    A post introducing “Rethinking at Fixed Points” asks whether looped language models could use 3× fewer parameters and a 3× smaller KV cache while remaining comparable to a standard Transformer. It argues that adding computing work could let the models scale without increasing memory use, and proposes fixed-point shortcuts, a learned depth prior and orthogonal injection.

    Combined views

    7.4K

    2 Sources, first seen 3h ago

    Combined views

    7.4K

    2 Sources, first seen 3h ago

    154 likes
    3h ago
    first seen 3h ago
    154 likes
    4 comments
    109 saves
    59 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    4 comments
    109 saves
    59 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    @huskydogewoof🔁 𝐖𝐡𝐚𝐭 𝐢𝐟 𝐥𝐨𝐨𝐩𝐞𝐝 𝐋𝐌𝐬 𝐜𝐨𝐮𝐥𝐝 𝐮𝐬𝐞 𝟑× 𝐟𝐞𝐰𝐞𝐫 𝐩𝐚𝐫𝐚𝐦𝐞𝐭𝐞𝐫𝐬 𝐚𝐧𝐝 𝐚 𝟑× 𝐬𝐦𝐚𝐥𝐥𝐞𝐫 𝐊𝐕 𝐜𝐚𝐜𝐡𝐞 𝐚𝐧𝐝 𝐬𝐭𝐢𝐥𝐥 𝐛𝐞 𝐜𝐨𝐦𝐩𝐚𝐫𝐚𝐛𝐥𝐞 𝐭𝐨 𝐚 𝐬𝐭𝐚𝐧𝐝𝐚𝐫𝐝 𝐓𝐫𝐚𝐧𝐬𝐟𝐨𝐫𝐦𝐞𝐫? Introducing 𝐑𝐞𝐭𝐡𝐢𝐧𝐤𝐢𝐧𝐠 𝐚𝐭 𝐅𝐢𝐱𝐞𝐝 𝐏𝐨𝐢𝐧𝐭𝐬. We argue that looped LMs don't have to pay for every loop. They can scale by adding FLOPs at constant memory. The key is the fixed point of the loop. We introduce: – 𝐅𝐢𝐱𝐞𝐝-𝐏𝐨𝐢𝐧𝐭 𝐒𝐡𝐨𝐫𝐭𝐜𝐮𝐭𝐬: what fixed points buy a looped model in training (pre-training, post-training) and inference (prefill, decoding) – A 𝐥𝐞𝐚𝐫𝐧𝐞𝐝 𝐝𝐞𝐩𝐭𝐡 𝐩𝐫𝐢𝐨𝐫 and 𝐨𝐫𝐭𝐡𝐨𝐠𝐨𝐧𝐚𝐥 𝐢𝐧𝐣𝐞𝐜𝐭𝐢𝐨𝐧: two ways to shape those fixed points 🧵 Long thread ahead (0/n).3h
    @ChengleiSiRT @huskydogewoof: 🔁 𝐖𝐡𝐚𝐭 𝐢𝐟 𝐥𝐨𝐨𝐩𝐞𝐝 𝐋𝐌𝐬 𝐜𝐨𝐮𝐥𝐝 𝐮𝐬𝐞 𝟑× 𝐟𝐞𝐰𝐞𝐫 𝐩𝐚𝐫𝐚𝐦𝐞𝐭𝐞𝐫𝐬 𝐚𝐧𝐝 𝐚 𝟑× 𝐬𝐦𝐚𝐥𝐥𝐞𝐫 𝐊𝐕 𝐜𝐚𝐜𝐡𝐞 𝐚𝐧𝐝 𝐬𝐭𝐢𝐥𝐥 𝐛𝐞 𝐜𝐨𝐦𝐩𝐚𝐫𝐚𝐛𝐥𝐞 𝐭𝐨 𝐚 𝐬𝐭𝐚𝐧𝐝𝐚𝐫𝐝 𝐓𝐫𝐚𝐧𝐬…1h