Announcement
AutoBenchmark tests human input in AI-generated research benchmarks
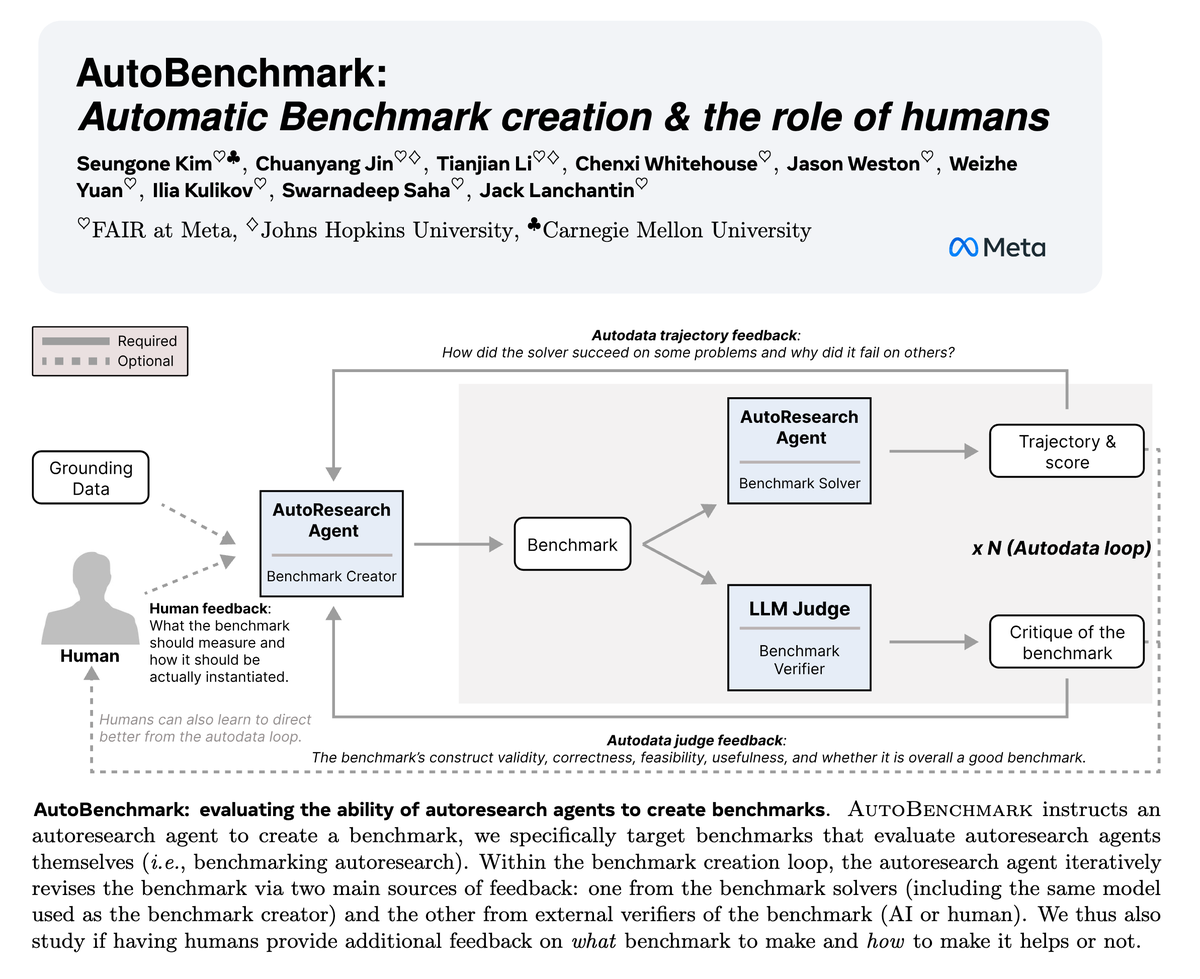
A thread introducing AutoBenchmark reports that detailed human guidance during the proposal stage worked better than a one-sentence idea or no human feedback in its tests.
TLDR
The AutoBenchmark thread describes a process in which agents propose benchmarks, other agents try to solve them, and an LLM reviews them. Its author reports that, in tests on two benchmarks, human feedback helped and detailed guidance worked better than a one-sentence idea. The thread also says human direction helped when an automated research loop stalled.
Combined views
35.1K
7 Sources, first seen 11h ago