AI
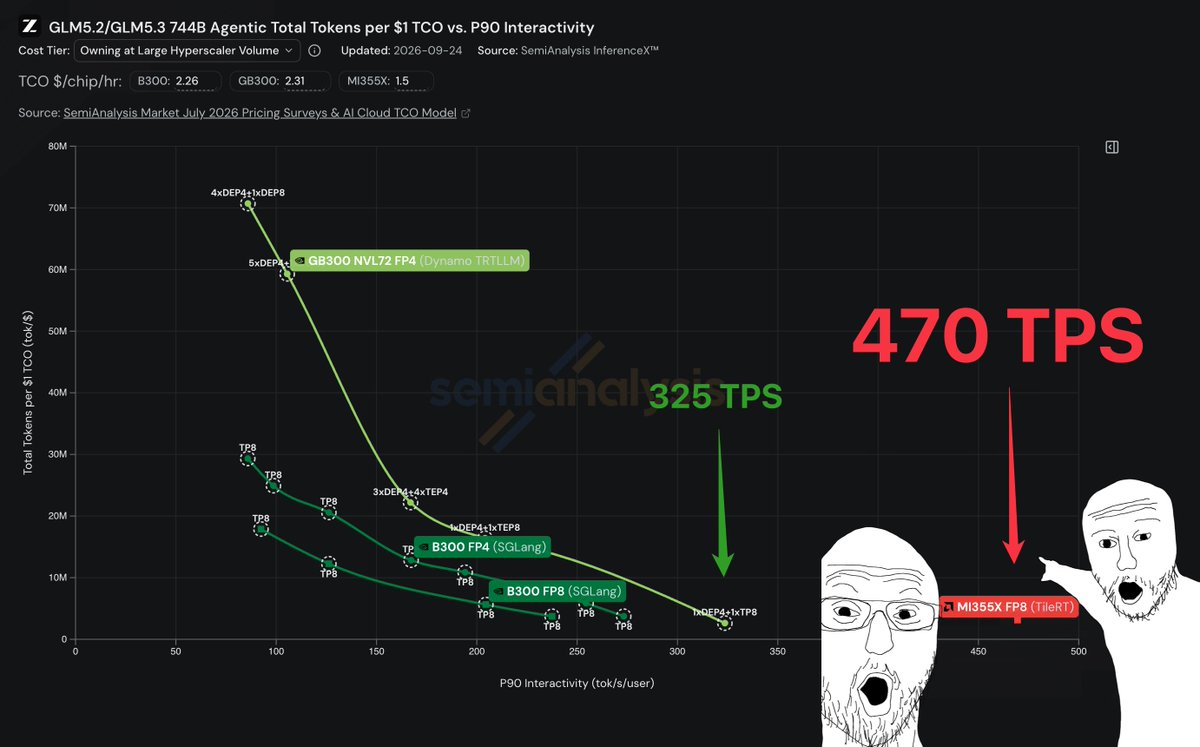
AMD MI355X with TileRT reportedly reaches 470 tokens per second on GLM 5.3 in FP8
SemiAnalysis says the setup uses vLLM to process prompts and TileRT to generate tokens, but flags high 90th-percentile time to first token compared with other engines.
TLDR
SemiAnalysis reports 470 tokens per second on GLM 5.3 in FP8 using AMD MI355X with TileRT—over 40% faster than GB300 running TRTLLM in FP4. It describes a split setup: vLLM handles prompt processing, while TileRT generates tokens using a persistent GPU kernel.
The publisher cautions that early results show high P90 time to first token—the 90th-percentile wait before output begins—compared with other engines. It expects optimizations to KV transfer and the addition of paged KV caching in the decode engine to improve that metric.
AMD MI355X with TileRT reportedly reaches 470 tokens per second on GLM 5.3 in FP8
SemiAnalysis says the setup uses vLLM to process prompts and TileRT to generate tokens, but flags high 90th-percentile time to first token compared with other engines.
TLDR
SemiAnalysis reports 470 tokens per second on GLM 5.3 in FP8 using AMD MI355X with TileRT—over 40% faster than GB300 running TRTLLM in FP4. It describes a split setup: vLLM handles prompt processing, while TileRT generates tokens using a persistent GPU kernel.
The publisher cautions that early results show high P90 time to first token—the 90th-percentile wait before output begins—compared with other engines. It expects optimizations to KV transfer and the addition of paged KV caching in the decode engine to improve that metric.