• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Report

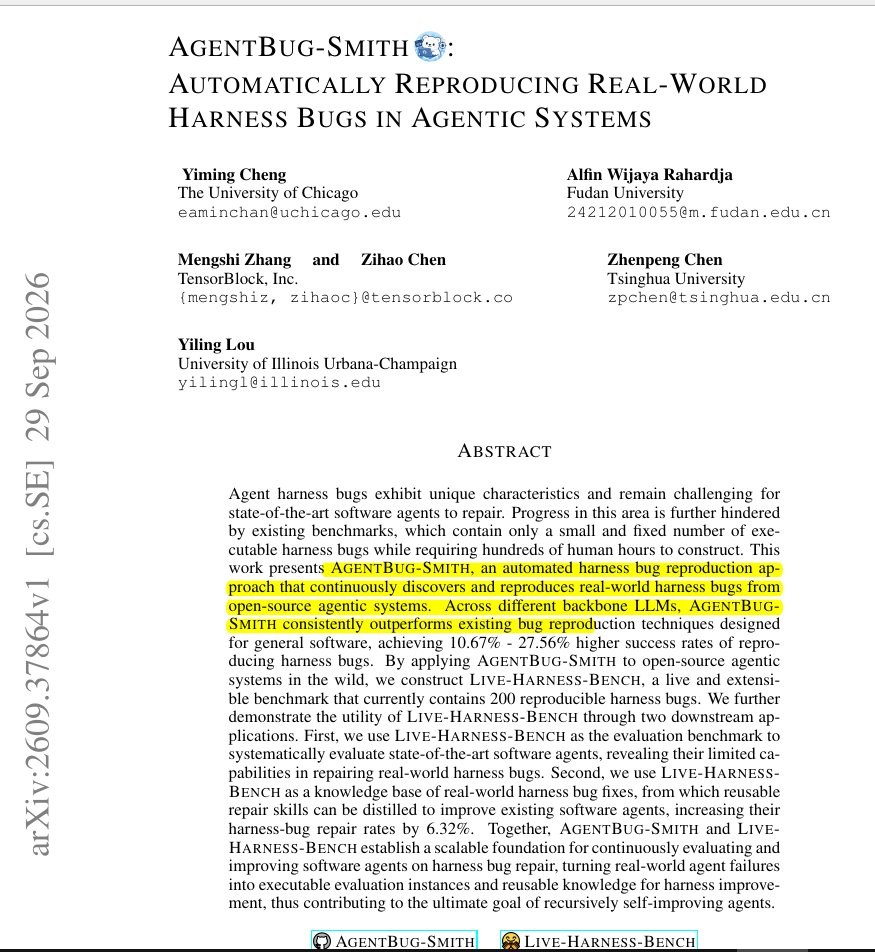
    AgentBug-Smith reportedly turns AI agent bug reports into runnable tests

    A post describing the research says its growing, 200-bug benchmark targets code handling agents’ tools, memory and prompts.

    RP
    2 Sources, 22h ago, first seen 22h ago

    TLDR

    A post describing AgentBug-Smith says researchers turned real GitHub bug reports about AI agents’ code into runnable tests for a growing, 200-bug benchmark. It says the best of three coding agents fixed just 9% of those bugs, compared with about 40% reported for regular software bugs. A short guide drawn from past fixes reportedly raised one agent’s score from one to six correct fixes on 79 unseen bugs.

    Combined views

    7K

    2 Sources, first seen 22h ago

    Combined views

    7K

    2 Sources, first seen 22h ago

    92 likes
    92 likes
    10 comments
    69 saves
    61 reposts
    10 comments
    69 saves
    61 reposts
    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    @rohanpaul_aiSelf-improving AI agents will need to fix their own code. And this paper from top US+China labs, shows coding agents miss most such bugs but improve with lessons from past fixes. that real bugs in agent harnesses, can be automatically turned into a growing set of runnable tests. An agent's own code is everything around the model: tool calls, memory, and prompts. Its bugs depend on live model calls, which makes them hard to recreate and test. So the researchers built AgentBug-Smith, which turns real GitHub bug reports into runnable tests. The result is a 200-bug benchmark that keeps growing. The best of 3 coding agents fixed just 9% of those bugs, versus about 40% reported on regular software bugs. A short guide of lessons from past fixes lifted an agent from 1 to 6 correct fixes on 79 unseen bugs. Before trusting a coding agent with your agent's code, try it on bugs you've already fixed.22h