Report
A code-based approach to grading AI agents when answers change
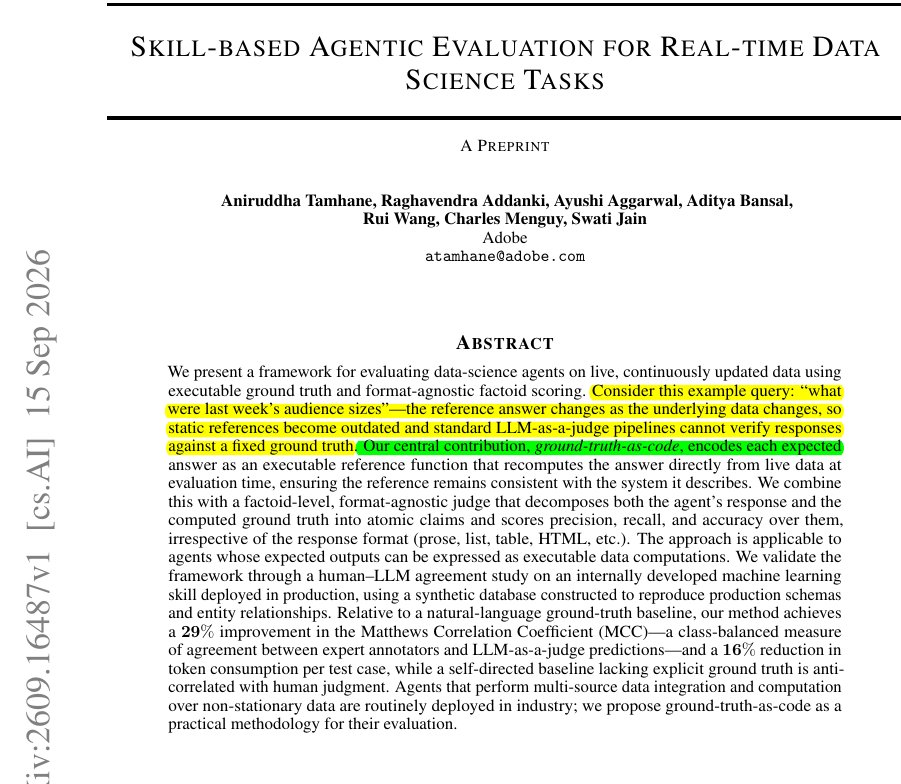
A post describes an Adobe paper that uses code to fetch the current answer for each test before an AI grader checks an agent’s reply.
TLDR
A post about an Adobe paper says agent tests can go stale when live data changes the right answer. The proposed method recalculates that answer each time a test runs, then has an AI grader check the agent’s reply. Across 53 test cases, the post says, the grader matched human experts 29% better than when given a written description and used 16% fewer tokens. Without an answer to check against, it did worse than random.
Combined views
2.7K
1 Source, first seen 7h ago