• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Company Knowledge Bench introduced to test retrieval on messy company knowledge

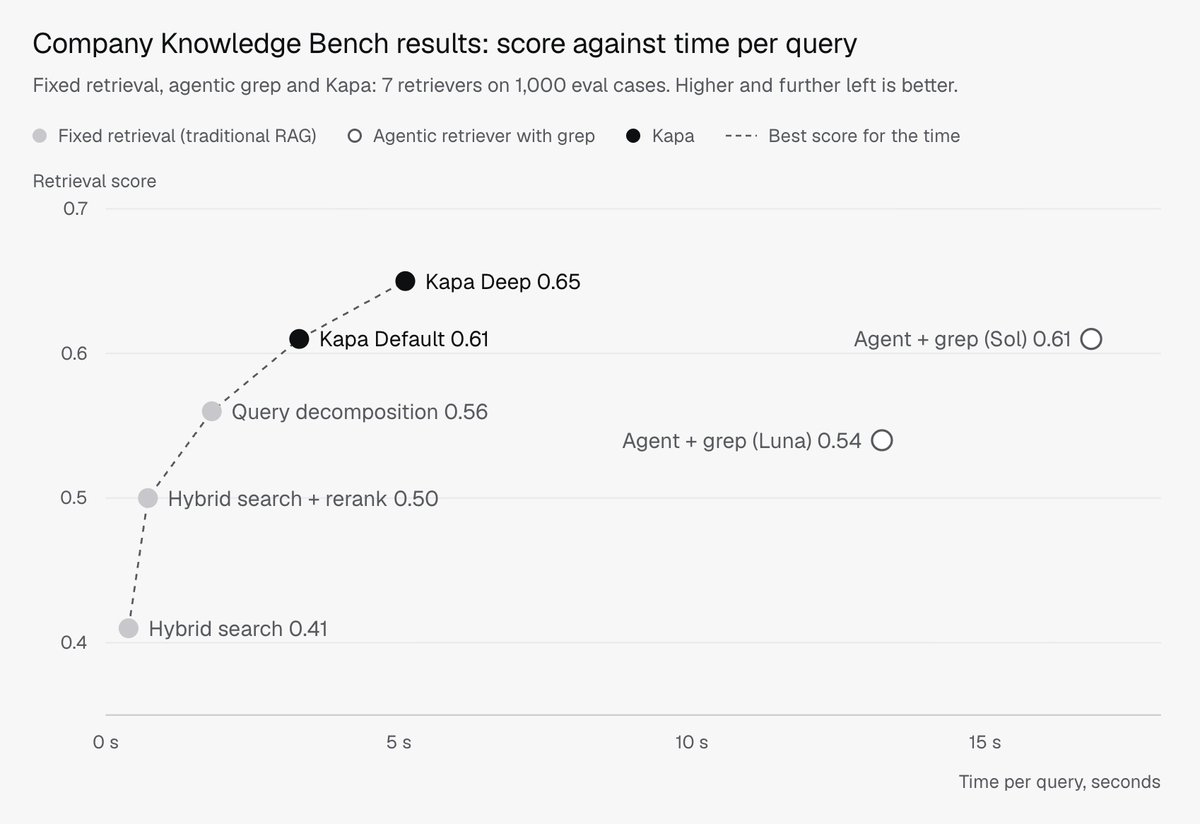
    The team behind it says it used 1,000 real-world queries to test seven retrievers, with Kapa Deep scoring highest.

    CS
    EM
    2 Sources, ,

    TLDR

    The team behind Company Knowledge Bench says it built the benchmark from 1,000 real-world queries by people and agents. In its tests of seven retrievers, grep worked surprisingly well but was five times slower and filled the context with 40,000 tokens per query. Kapa Deep scored highest at 0.65 in about five seconds, using one-eighth as many tokens.

    Combined views

    2.5K

    2 Sources, first seen 8h ago

    Combined views

    2.5K

    2 Sources, first seen 8h ago

    33 likes
    8h ago
    first seen 8h ago
    33 likes
    4 comments
    23 saves
    10 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    4 comments
    23 saves
    10 reposts

    2 Sources

    @emilsnotesintroducing Company Knowledge Bench the first retrieval benchmark built on messy, real-world company knowledge soon agents will do a huge share of the work inside every company. all of it starts with finding the right information, but almost nobody can measure how well their agents actually find it public benchmarks don't help. they're either one narrow domain like law or medicine, or synthetic documents and questions. real company knowledge is messy, contradicts itself and goes out of date retrieval is the core of @kapa_ai, so we spent months building our own benchmark from 1,000 real-world queries by people and agents then we ran 7 retrievers on it: 1/ grep works surprisingly well, but it's 5x slower and floods the context with 40K tokens per query 2/ optimized agentic retrievers do far better. Kapa Deep scored highest (0.65) in ~5s with an eighth of the tokens 3/ we're still very early. lots of headroom left, especially as more agents run on company knowledge full write-up below8h
    @CShorten30RT @emilsnotes: introducing Company Knowledge Bench the first retrieval benchmark built on messy, real-world company knowledge soon agent…7h

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    2 Sources

    @emilsnotesintroducing Company Knowledge Bench the first retrieval benchmark built on messy, real-world company knowledge soon agents will do a huge share of the work inside every company. all of it starts with finding the right information, but almost nobody can measure how well their agents actually find it public benchmarks don't help. they're either one narrow domain like law or medicine, or synthetic documents and questions. real company knowledge is messy, contradicts itself and goes out of date retrieval is the core of @kapa_ai, so we spent months building our own benchmark from 1,000 real-world queries by people and agents then we ran 7 retrievers on it: 1/ grep works surprisingly well, but it's 5x slower and floods the context with 40K tokens per query 2/ optimized agentic retrievers do far better. Kapa Deep scored highest (0.65) in ~5s with an eighth of the tokens 3/ we're still very early. lots of headroom left, especially as more agents run on company knowledge full write-up below8h
    @CShorten30RT @emilsnotes: introducing Company Knowledge Bench the first retrieval benchmark built on messy, real-world company knowledge soon agent…7h
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet