• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Synthetic pre-pretraining reportedly improves language-model efficiency at scale, without a clear grammar link

    Researchers tested brief training on synthetic, non-natural-language data before pre-training models ranging from 500M to 7B parameters.

    AL
    AY
    2 Sources, ,

    TLDR

    In a September 30 preprint, researchers report that briefly training language models on synthetic, non-natural-language data before pre-training improves downstream performance and token efficiency at larger scales. They estimate savings of at least 21B pre-training tokens at the 3B-parameter scale. They find no consistent evidence that the gains come from a grammatical prior, instead linking downstream gains to tasks that improve long-range retrieval.

    Combined views

    13.9K

    2 Sources, first seen 20h ago
    Combined views

    13.9K

    2 Sources, first seen 20h ago

    125 likes
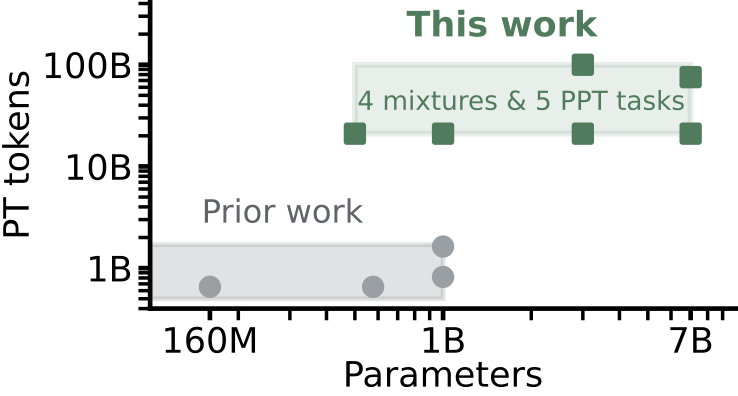
    Prior work sits at or below 1B parameters and short training horizons. We span four scales, four PT mixtures, five PPT tasks, and up to 100B PT tokens to test the effectiveness of PPT in a more realistic setting.
    20h ago
    first seen 20h ago
    125 likes
    5 comments
    95 saves
    20 reposts
    Featured Source
    5 comments
    95 saves
    20 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    2 Sources

    @_gucciiiiiA last piece of my PhD work is out! https://arxiv.org/abs/2609.39827 We ask whether "pre-pretraining" (PPT) (i.e., training on synthetic non-natural language data briefly prior to pre-training on natural language data) helps at scale. This is the largest ever PPT study! (1/5)
    @AndrewLampinenRT @_gucciiiii: A last piece of my PhD work is out! https://arxiv.org/abs/2609.39827 We ask whether "pre-pretraining" (PPT) (i.e., training on syn…

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    @_gucciiiiiA last piece of my PhD work is out! https://arxiv.org/abs/2609.39827 We ask whether "pre-pretraining" (PPT) (i.e., training on synthetic non-natural language data briefly prior to pre-training on natural language data) helps at scale. This is the largest ever PPT study! (1/5)
    @AndrewLampinenRT @_gucciiiii: A last piece of my PhD work is out! https://arxiv.org/abs/2609.39827 We ask whether "pre-pretraining" (PPT) (i.e., training on syn…