• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Fast Metal kernels in llama.cpp now cover all 26 Mac GPU weight formats

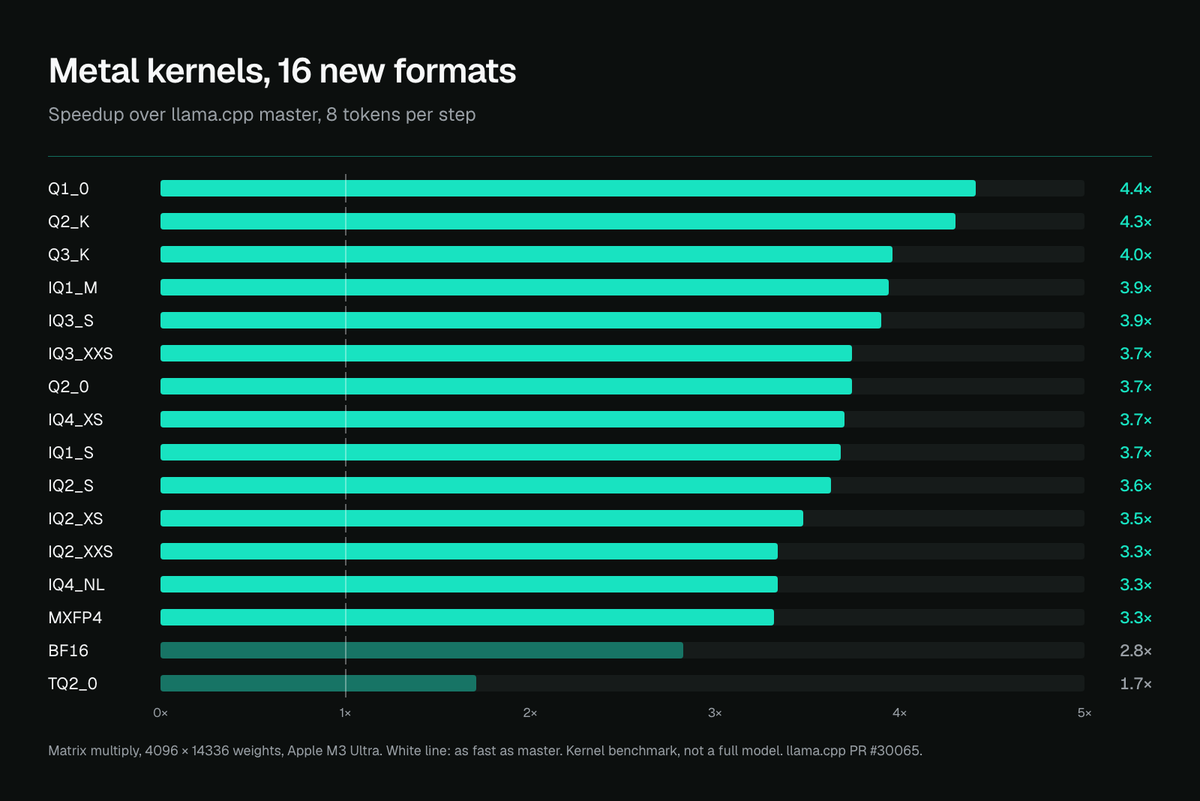
    The contributor says the latest PR added 16 formats, including BF16 and MXFP4, to the 10 covered earlier.

    Georgi GerganovGG
    QVACQV
    2 Sources, ,

    TLDR

    The contributor says a newly merged llama.cpp PR extends fast Metal kernels from 10 Mac GPU weight formats to all 26, including BF16, MXFP4, Q2_K, Q3_K and IQ quants. They say the earlier kernels sped up speculative decoding for 10 formats, while matrix multiplies on an M3 Ultra run up to 4.4 times faster when a model checks several tokens at once.

    Combined views

    4K

    2 Sources, first seen 10h ago

    Combined views

    4K

    2 Sources, first seen 10h ago

    27 likes
    10h ago
    first seen 10h ago
    27 likes
    2 comments
    1 saves
    7 reposts
    2 comments
    1 saves
    7 reposts
    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    QVAC@qvacAnother PR of ours just merged into llama.cpp: the fast Metal kernels from Monday now cover all 26 weight formats the Mac GPU runs. They made speculative decoding faster on Mac for 10 formats, and this PR adds the other 16, including BF16, MXFP4, Q2_K, Q3_K and the IQ quants. On an M3 Ultra, matrix multiplies run up to 4.4x faster when a model checks several tokens at once. Thanks @ggerganov for asking for it and merging it within a day. http://github.com/ggml-org/llama.cpp/pull/3006510h
    Georgi Gerganov@ggerganovRT @qvac: Another PR of ours just merged into llama.cpp: the fast Metal kernels from Monday now cover all 26 weight formats the Mac GPU run…1h