AI
Self-play pretraining reportedly scales without real training data
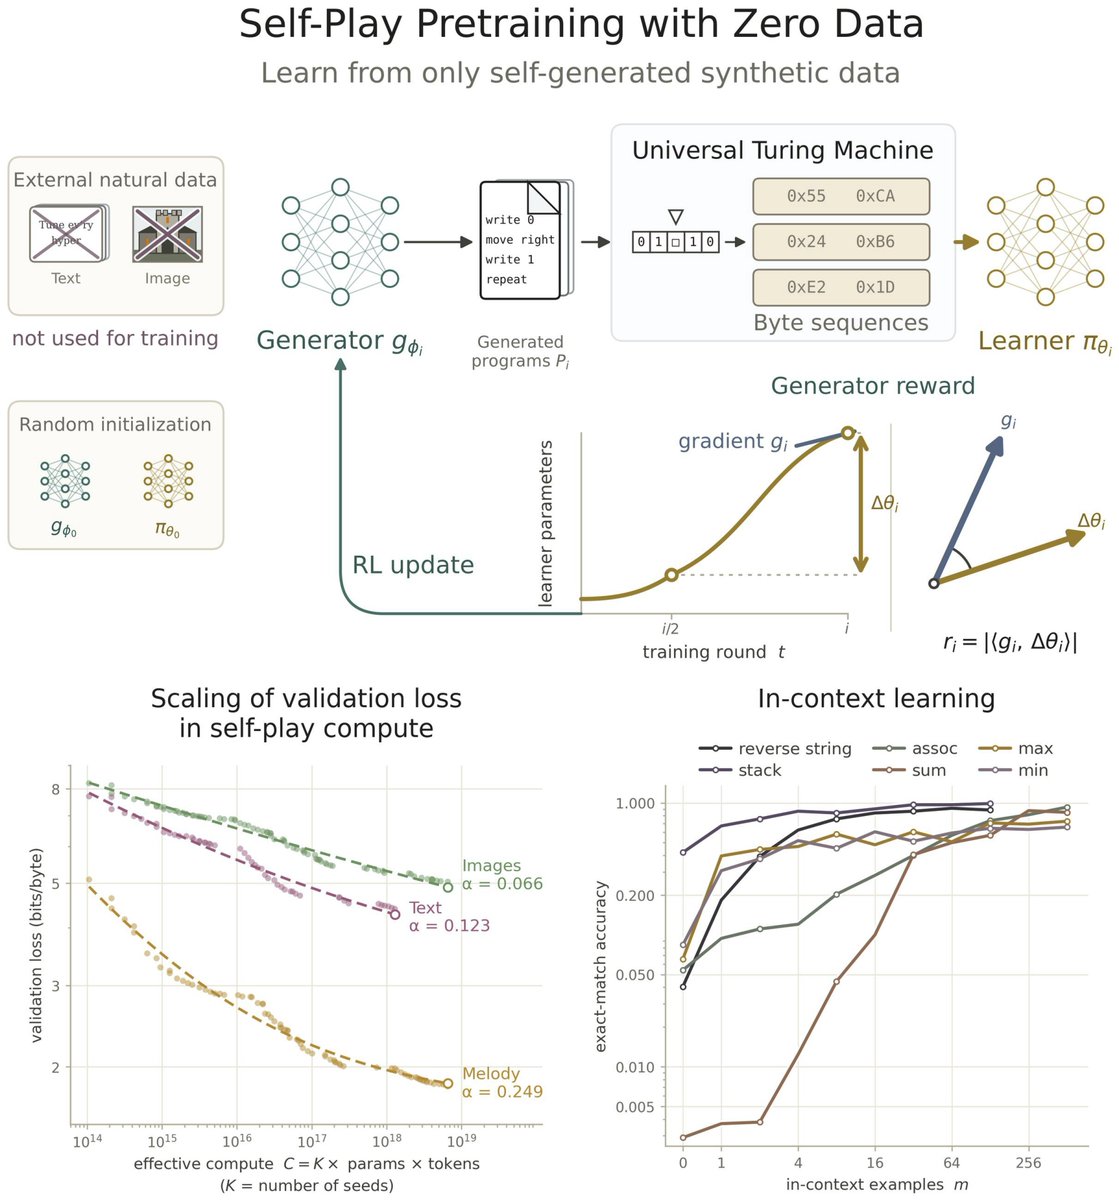
A researcher introducing “Self-Play Pretraining with Zero Data” says two models start from random initialization: a generator proposes programs, and a learner trains on their outputs.
TLDR
A researcher describes “Self-Play Pretraining with Zero Data” as a proof of concept using two randomly initialized models. A generator proposes programs for a universal Turing machine, and a learner trains on their outputs. The team says it never trains on real data. The researcher reports that zero-shot validation loss on natural datasets—images, text, audio and melodies—decreases predictably as self-play compute increases. They also report that the learner develops in-context learning capabilities.
Self-play pretraining reportedly scales without real training data
A researcher introducing “Self-Play Pretraining with Zero Data” says two models start from random initialization: a generator proposes programs, and a learner trains on their outputs.