• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    ‘Reasoning from Scratch’ returns with an RLVR and GRPO walkthrough

    Sebastian Raschka’s sixth installment moves from reward concepts to a training loop and MATH-500 evaluation.

    SR
    1 Source, 9h ago, first seen 9h ago

    TLDR

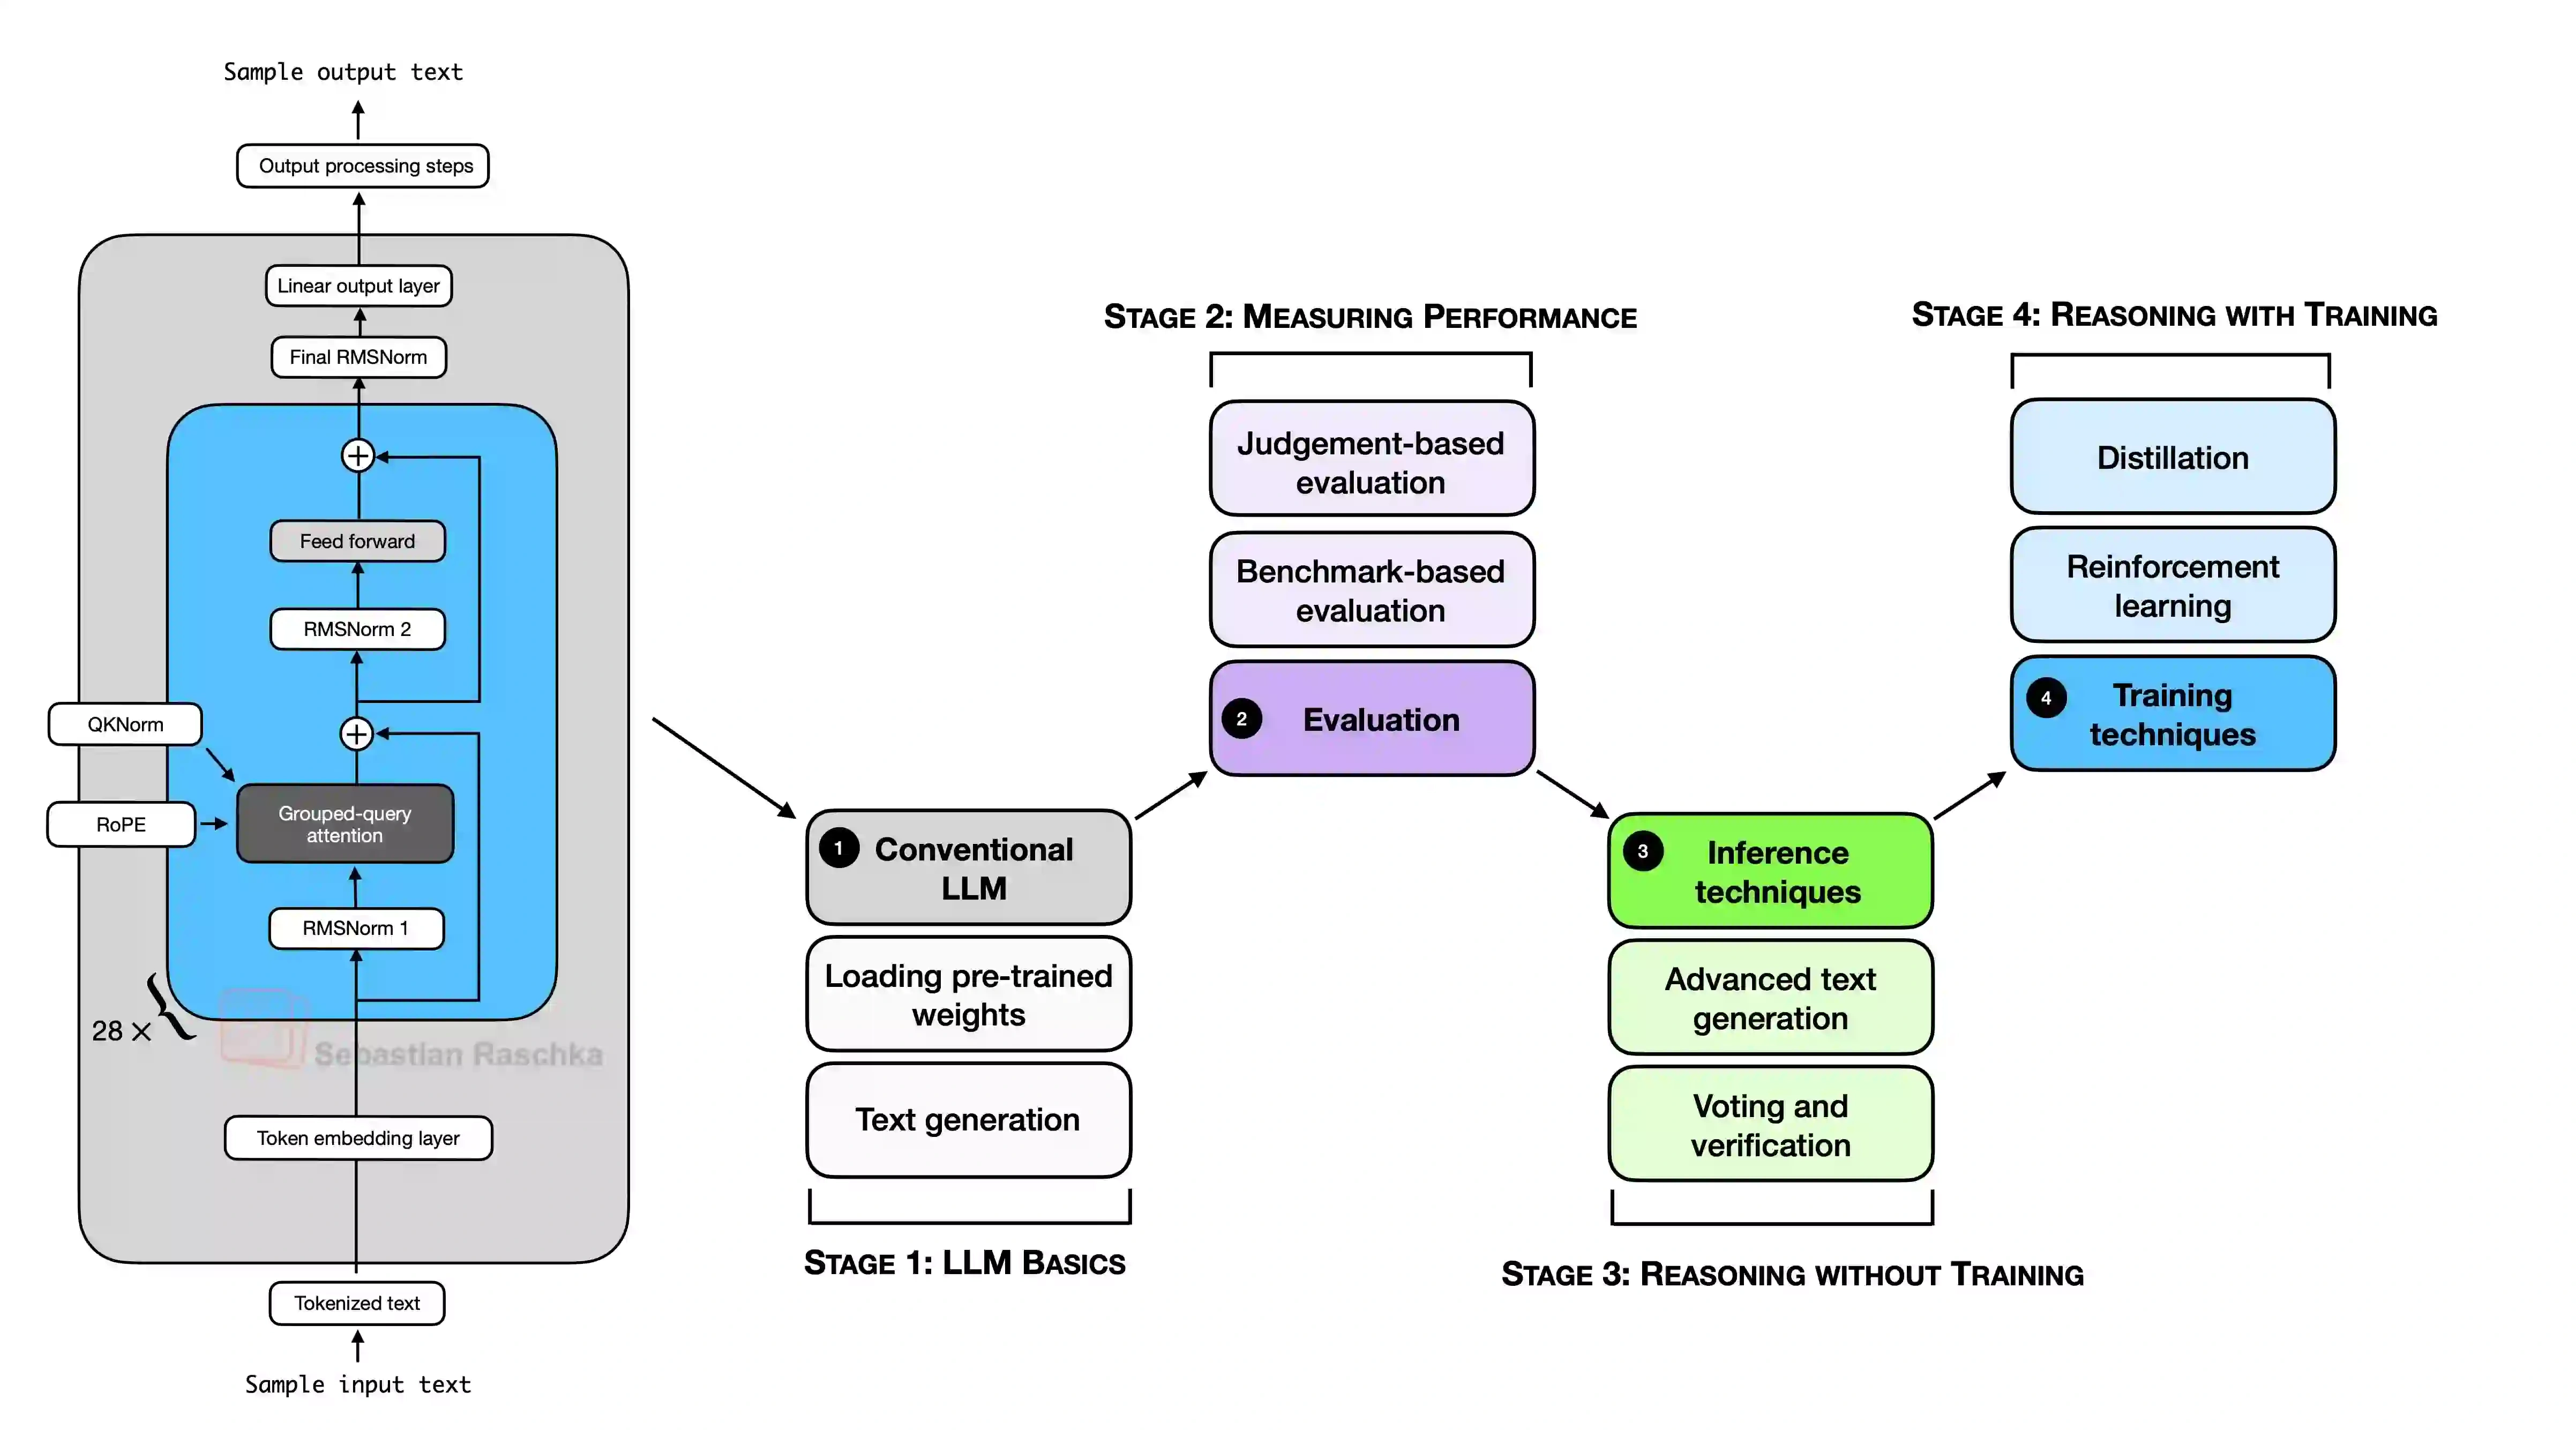
    Sebastian Raschka’s sixth “Reasoning from Scratch” installment introduces and implements reinforcement learning with verifiable rewards and group relative policy optimization. Its chapter list moves from reasoning traces, reward types and GRPO concepts to loading a model and data, computing the loss, running a training loop and evaluating checkpoints with MATH-500 and stability checks.

    Combined views

    36K

    1 Source, first seen 9h ago

    Combined views

    36K

    1 Source, first seen 9h ago

    943 likes

    Useful links

    Sebastian Raschka, PhD

    Build a Reasoning Model (From Scratch)

    Sebastian Raschka · YouTube

    Build A Reasoning Model From Scratch 6: Reinforcement Learning 1 (Implementing GRPO for RLVR)

    Substack

    Sebastian Raschka, PhD (@rasbt)

    Sebastian Raschka · YouTube

    Build A Reasoning Model From Scratch 3: The Verifier for Evaluation and RL with Verifiable Rewards
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    943 likes
    39 comments
    875 saves
    89 reposts
    39 comments
    875 saves
    89 reposts

    1 Source

    @rasbtReasoning from scratch, round number 6! An introduction (and implementation) of Reinforcement Learning with Verifiable Rewards (RLVR) and Group Relative Policy Optimization (GRPO). 00:00 Introduction 01:54 What makes a reasoning model different? 04:25 Reasoning traces and model capability 08:29 Accuracy and format rewards 11:34 Aha moments and DeepSeek-R1 training 14:41 Reasoning effort and answer length 18:38 RLHF and RLVR 23:04 GRPO vs. PPO 26:40 GRPO explained with a cooking analogy 31:43 The KL term and simplified GRPO 35:04 Loading the pretrained model 36:07 Loading the MATH training data 39:26 Sampling model responses 46:30 Computing verifiable rewards 49:55 Computing advantages 51:54 Token and sequence log probabilities 55:29 Implementing sequence log probabilities 57:37 Fixing the inference-mode error 1:02:24 Computing the GRPO loss 1:04:37 Putting the GRPO step together 1:09:19 The GRPO training loop 1:12:57 Training settings, logging, and checkpoints 1:17:24 Running training and inspecting outputs 1:19:28 Loading and evaluating checkpoints 1:22:33 MATH-500 results and training stability 1:24:05 Memory requirements and next steps9h

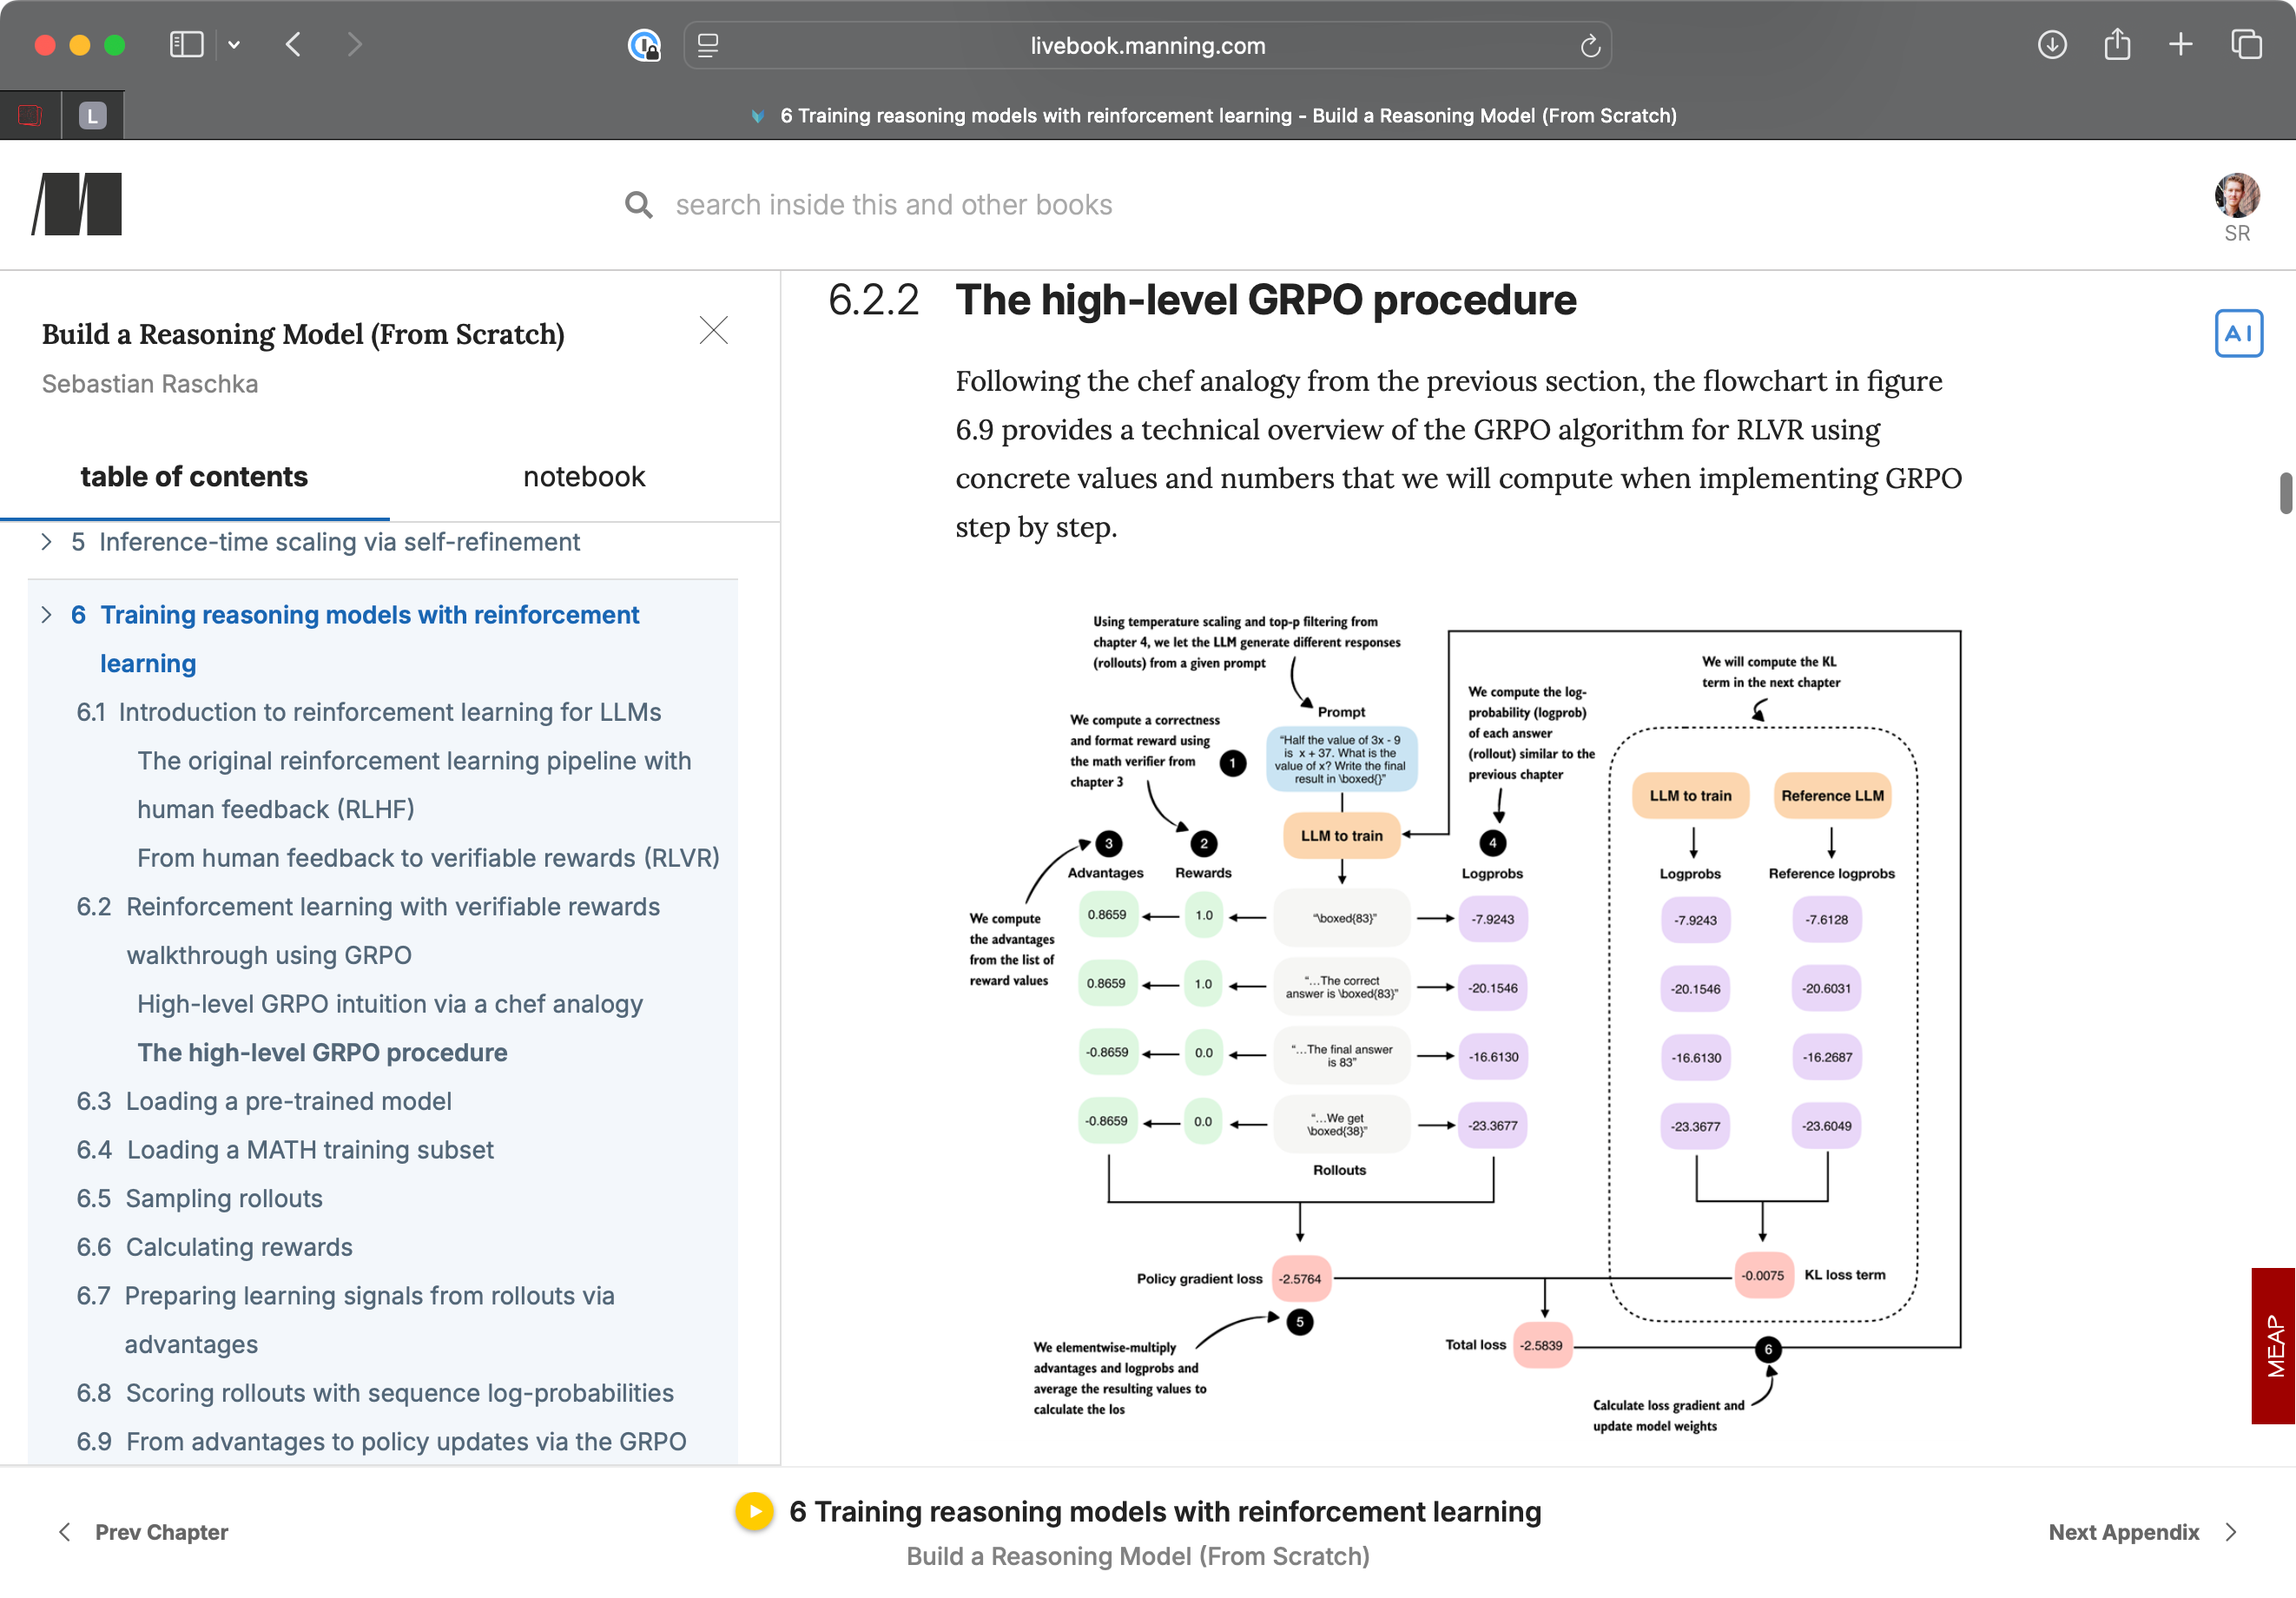
    Sebastian Raschka’s sixth “Reasoning from Scratch” installment introduces and implements reinforcement learning with verifiable rewards, or RLVR, and group relative policy optimization, or GRPO.

    From reasoning traces to GRPO

    The chapter list begins with what makes a reasoning model different, then covers reasoning traces, model capability, accuracy and format rewards, DeepSeek-R1 training, and reasoning effort and answer length.

    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Useful Links

    Sebastian Raschka, PhD

    Build a Reasoning Model (From Scratch)

    Substack

    Sebastian Raschka, PhD (@rasbt)

    Related Videos

    • Build A Reasoning Model From Scratch 6: Reinforcement Learning 1 (Implementing GRPO for RLVR)Sebastian Raschka · YouTube
    • Build A Reasoning Model From Scratch 3: The Verifier for Evaluation and RL with Verifiable RewardsSebastian Raschka · YouTube

    1 Source

    @rasbtReasoning from scratch, round number 6! An introduction (and implementation) of Reinforcement Learning with Verifiable Rewards (RLVR) and Group Relative Policy Optimization (GRPO). 00:00 Introduction 01:54 What makes a reasoning model different? 04:25 Reasoning traces and model capability 08:29 Accuracy and format rewards 11:34 Aha moments and DeepSeek-R1 training 14:41 Reasoning effort and answer length 18:38 RLHF and RLVR 23:04 GRPO vs. PPO 26:40 GRPO explained with a cooking analogy 31:43 The KL term and simplified GRPO 35:04 Loading the pretrained model 36:07 Loading the MATH training data 39:26 Sampling model responses 46:30 Computing verifiable rewards 49:55 Computing advantages 51:54 Token and sequence log probabilities 55:29 Implementing sequence log probabilities 57:37 Fixing the inference-mode error 1:02:24 Computing the GRPO loss 1:04:37 Putting the GRPO step together 1:09:19 The GRPO training loop 1:12:57 Training settings, logging, and checkpoints 1:17:24 Running training and inspecting outputs 1:19:28 Loading and evaluating checkpoints 1:22:33 MATH-500 results and training stability 1:24:05 Memory requirements and next steps9h

    It then compares reinforcement learning from human feedback with RLVR, and GRPO with proximal policy optimization. Raschka also includes a cooking analogy for GRPO, followed by the KL term and a simplified version of the method.

    Building the training loop

    The implementation section loads a pretrained model and MATH training data, samples responses, and computes verifiable rewards, advantages, and token and sequence log probabilities. It then implements the GRPO loss, assembles a GRPO step and builds the training loop.

    The final chapters cover settings, logging and checkpoints, along with running training and inspecting outputs. The installment closes with checkpoint evaluation, MATH-500 results, training stability, memory requirements and next steps.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Useful Links

    Sebastian Raschka, PhD

    Build a Reasoning Model (From Scratch)

    Related Videos

    Substack

    Sebastian Raschka, PhD (@rasbt)
    Build A Reasoning Model From Scratch 6: Reinforcement Learning 1 (Implementing GRPO for RLVR)Sebastian Raschka · YouTube
  • Build A Reasoning Model From Scratch 3: The Verifier for Evaluation and RL with Verifiable RewardsSebastian Raschka · YouTube