AI
RSIAgent reportedly averages 74.54% on four tasks with broad-first practice
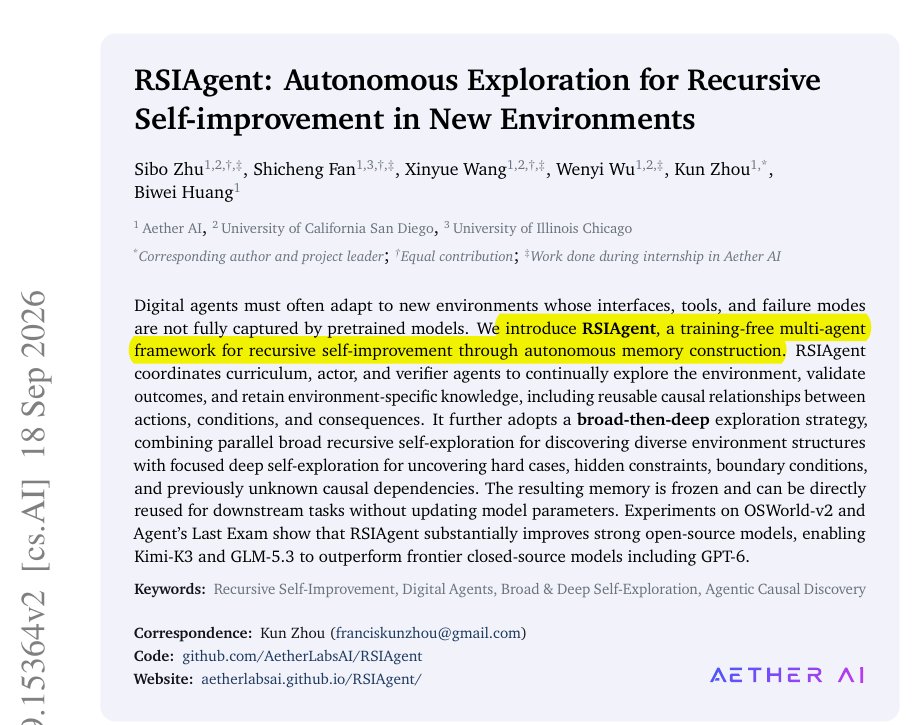
A post summarizing the RSIAgent paper describes a three-part practice loop: one agent invents tasks, another solves them with code, and a separate verifier checks the results.
TLDR
A user summarizing the RSIAgent paper reports that agents exploring broadly before tackling hard cases averaged 74.54% on four tasks, versus 56.50% when they went straight to the hard cases. The post describes practice starting with related tasks before focusing on the real task and its difficult cases. A curriculum agent creates practice tasks, an actor solves them with code, and a separate verifier checks results and decides what gets saved.
RSIAgent reportedly averages 74.54% on four tasks with broad-first practice
A post summarizing the RSIAgent paper describes a three-part practice loop: one agent invents tasks, another solves them with code, and a separate verifier checks the results.
TLDR
A user summarizing the RSIAgent paper reports that agents exploring broadly before tackling hard cases averaged 74.54% on four tasks, versus 56.50% when they went straight to the hard cases. The post describes practice starting with related tasks before focusing on the real task and its difficult cases. A curriculum agent creates practice tasks, an actor solves them with code, and a separate verifier checks results and decides what gets saved.