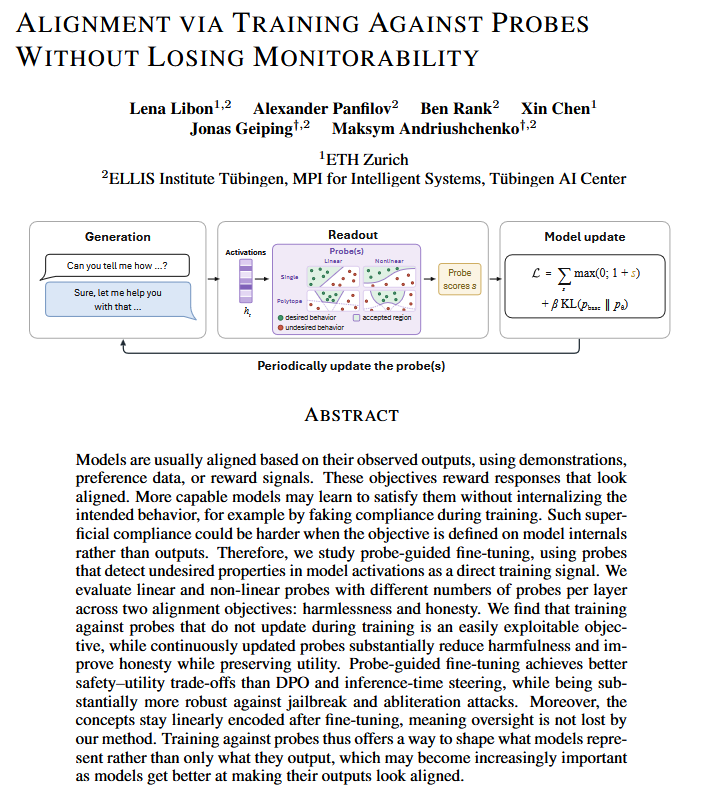
Paper explores probe-based training for AI alignment
The researchers report robustness and out-of-distribution harmfulness results while keeping the model monitorable.
TLDR
Researchers describe training against internal probes to improve a model’s alignment while preserving white-box monitoring. In one harmfulness test, they say probes were trained on BeaverTails, the model was rolled out on JBB, and evaluation on ClearHarm showed out-of-distribution generalization. The team says its model remained robust and monitorable, though before-and-after monitorability results across all data splits were still to be added.
Combined views
13.1K
10 Sources, first seen ago