Announcement
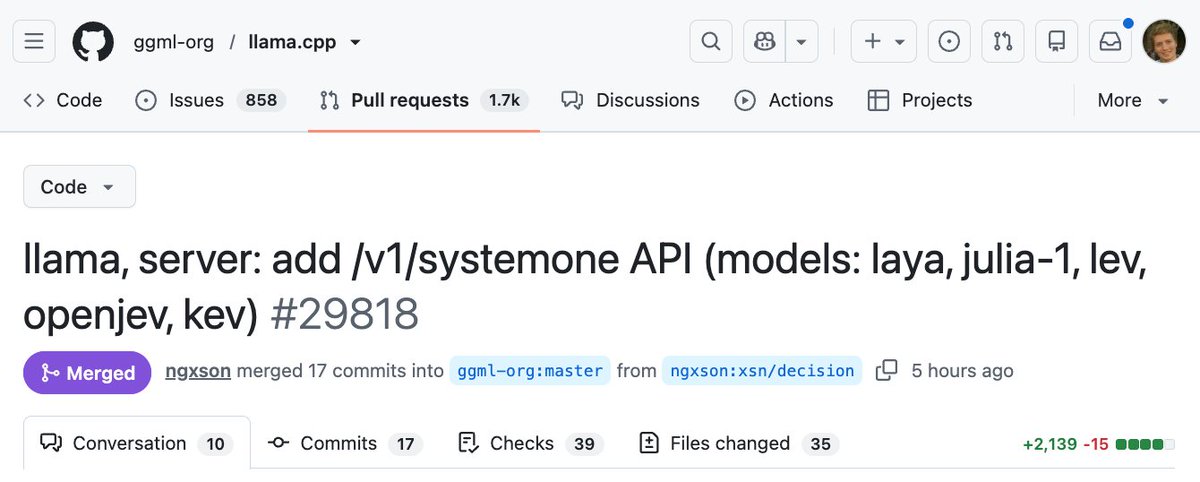
Decision models now run on-device in llama.cpp
A post calls the on-device option free, fast and private, and shares a command using Kev-4B-GGUF.
TLDR
A post says decision models now run on-device in llama.cpp, describing the option as free, fast and private. It shares the command llama serve -hf ggml-org/Kev-4B-GGUF.
Combined views
24.2K
1 Source, first seen ago
likes