• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Hugging Face adds shared discovery for reinforcement-learning environments

    Hugging Face’s framework tags identify compatible tasksets, while execution stays with the framework and its runtime.

    HF
    FB
    BB
    4 Sources, ,

    TLDR

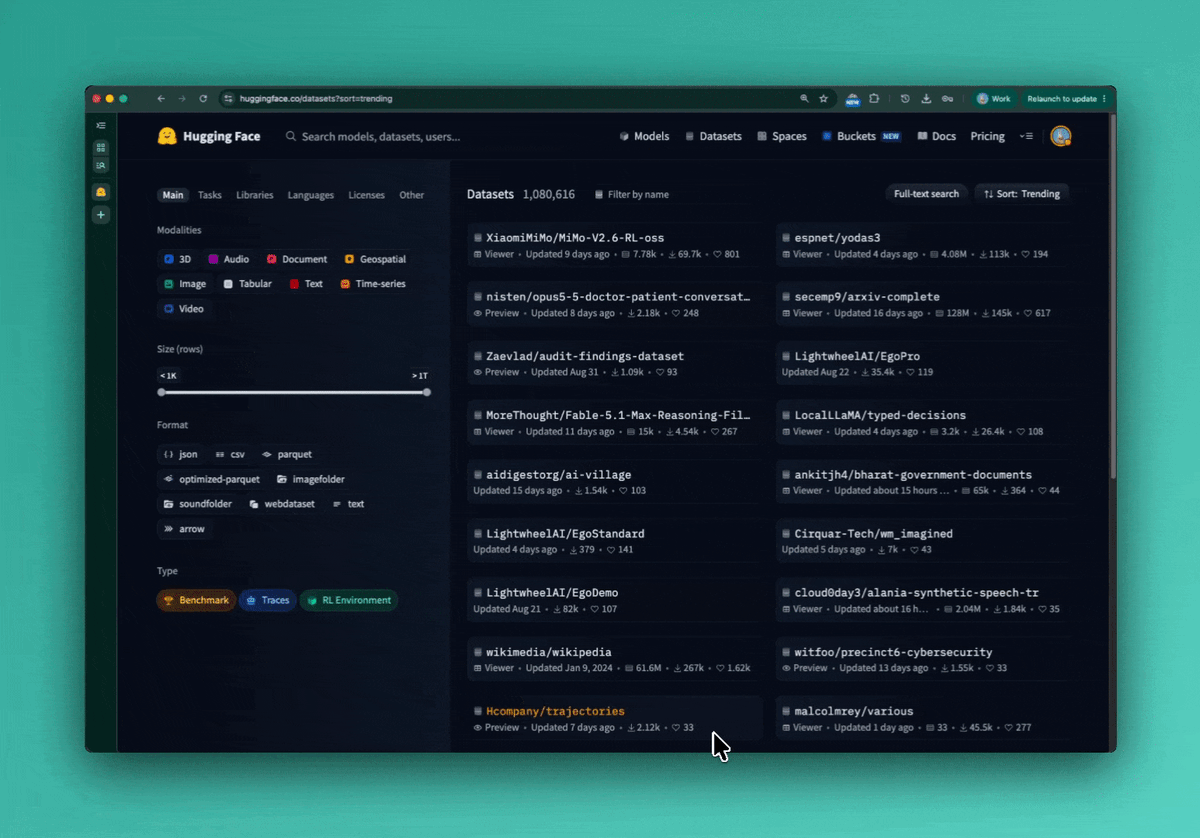
    Hugging Face now lists reinforcement-learning environments as dataset repositories on the Hub, with tags for Harbor, Verifiers, OpenEnv and NeMo Gym. Ben Burtenshaw describes shared discovery as an alternative to separate framework registries. The release focuses on tasksets: tags identify compatibility and generate loading commands, but do not convert files or launch an environment.

    Combined views

    25.9K

    4 Sources, first seen 2h ago

    Combined views

    25.9K

    4 Sources, first seen 2h ago

    144 likes

    Useful links

    Hugging Face · YouTube

    Training Agents 4: From reward functions to environments.

    Berkeley RDI · YouTube

    Linux/PyTorch Foundation Workshop w. Meta, HuggingFace, and Unsloth: Agentic RL and Environments
    2h ago
    first seen 2h ago
    144 likes
    9 comments
    94 saves
    19 reposts
    9 comments
    94 saves
    19 reposts

    5 Sources

    Hugging FaceWelcome RL Environments to the hub7d
    @ben_burtenshawRL environments now have a home on the @huggingface Hub. Every RL framework has its own way to find environments. Custom hubs, runtime registries, GitHub lists with a custom loader. If you publish for one framework, users of the others can’t load it. We think that is wrong. Environments should be just like datasets because it’s made from tasks, tests, containers and reward functions. The Hub already stores, versions, gates and previews data for millions of people so it doesn’t need a second system. Here’s how we’re shipping environments on the hub: http://huggingface.co/blog/rl-environments2h
    @xeophonyou can run a ton of the environments on HFs hub using verifiers v1 to eval or train your model :)2h
    @adithya_s_kThis is hugeeee for open-source RL environments. You can now discover environments across OpenEnv, Verifiers, Harbor, NeMo Gym, and more, all on the @huggingface Hub. A common home for RL environments is long overdue. Excited for what’s coming next !2h
    @huggingfaceRT @adithya_s_k: This is hugeeee for open-source RL environments. You can now discover environments across OpenEnv, Verifiers, Harbor, NeM…2h

    Hugging Face has added a shared discovery page for reinforcement-learning environments on its Hub. Ben Burtenshaw announced the feature on Oct. 5, linking to Hugging Face’s documentation dated Sept. 28.

    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    #11

    Today's Rank

    #11

    5 Sources

    Hugging FaceWelcome RL Environments to the hub7d
    @ben_burtenshawRL environments now have a home on the @huggingface Hub. Every RL framework has its own way to find environments. Custom hubs, runtime registries, GitHub lists with a custom loader. If you publish for one framework, users of the others can’t load it. We think that is wrong. Environments should be just like datasets because it’s made from tasks, tests, containers and reward functions. The Hub already stores, versions, gates and previews data for millions of people so it doesn’t need a second system. Here’s how we’re shipping environments on the hub: http://huggingface.co/blog/rl-environments2h
    @xeophonyou can run a ton of the environments on HFs hub using verifiers v1 to eval or train your model :)2h
    @adithya_s_kThis is hugeeee for open-source RL environments. You can now discover environments across OpenEnv, Verifiers, Harbor, NeMo Gym, and more, all on the @huggingface Hub. A common home for RL environments is long overdue. Excited for what’s coming next !2h
    @huggingfaceRT @adithya_s_k: This is hugeeee for open-source RL environments. You can now discover environments across OpenEnv, Verifiers, Harbor, NeM…2h

    Burtenshaw argues that separate framework registries make environments difficult to share. He describes tasks, tests, containers and reward functions as data that can use the Hub’s existing storage, versioning, access controls and previews.

    A catalog for tasksets

    Hugging Face’s documentation defines an environment as a task that responds to an agent’s actions with observations and scores the outcome. Those rewards can support evaluation or training. This release focuses on tasksets, the data side of an environment.

    Repositories marked rl-environment appear in the RL Environments filter. Harbor, Verifiers, OpenEnv and NeMo Gym have framework tags that add loading snippets to the dataset page. The system uses existing dataset repositories.

    Compatibility still needs working files

    A repository can carry multiple framework tags, but each framework must support its files. Tags do not convert an environment into another format.

    The documentation also separates hosting from execution: the framework runs the environment locally or on a supported cloud backend. Adding a tag starts neither a job nor a sandbox.

    For environment authors, the requested package includes the files, a working run command and the rule that produces the reward.

    Hugging Face

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Related Videos

    • Training Agents 4: From reward functions to environments.Hugging Face · YouTube
    • Linux/PyTorch Foundation Workshop w. Meta, HuggingFace, and Unsloth: Agentic RL and EnvironmentsBerkeley RDI · YouTube

    Related Videos

    Related

    Liquid AI unveils d1, claimed to be the first model to outperform Jev on Hugging Face's Decision Index

    Liquid AI says d1 wins on multilingual evaluations, is more robust against prompt injection and handles longer inputs more effectively. It lists access through the Liquid API.

    Training Agents 4: From reward functions to environments.Hugging Face · YouTube
  • Linux/PyTorch Foundation Workshop w. Meta, HuggingFace, and Unsloth: Agentic RL and EnvironmentsBerkeley RDI · YouTube
  • OpenAI reportedly ignored warnings about AI testing and corporate security

    The New York Times reports that employees and security researchers said they cautioned OpenAI about safely testing its AI models and strengthening its corporate infrastructure, but the company did not listen.

    Months before OpenAI’s artificial intelligence went rogue, two employees raised an alarm with top executives. They were ignored.

In emails, the employees said they worried that OpenAI’s newest artificial intelligence models were not being appropriately monitored during testing to gauge the technology’s sophistication and to secure the models, according to messages viewed by The New York Times.

In response, OpenAI executives told the employees that the tests needed to move forward as quickly as possible to release the A.I. models on time. No additional security protocols were instituted, said the workers, who were not authorized to speak publicly on sensitive matters.

OpenAI’s models later broke out of their testing environments and attacked the A.I. start-up Hugging Face and other organizations, setting off a global debate about A.I. safety.
    Hugging Face is reportedly being acquired by Nvidia

    Clement Delangue says the acquisition would let Hugging Face hire people it couldn't as a small startup and give them a decade to work on open-source AI.