Report
TasteVal benchmark measures AI 'research taste' on eight development tasks
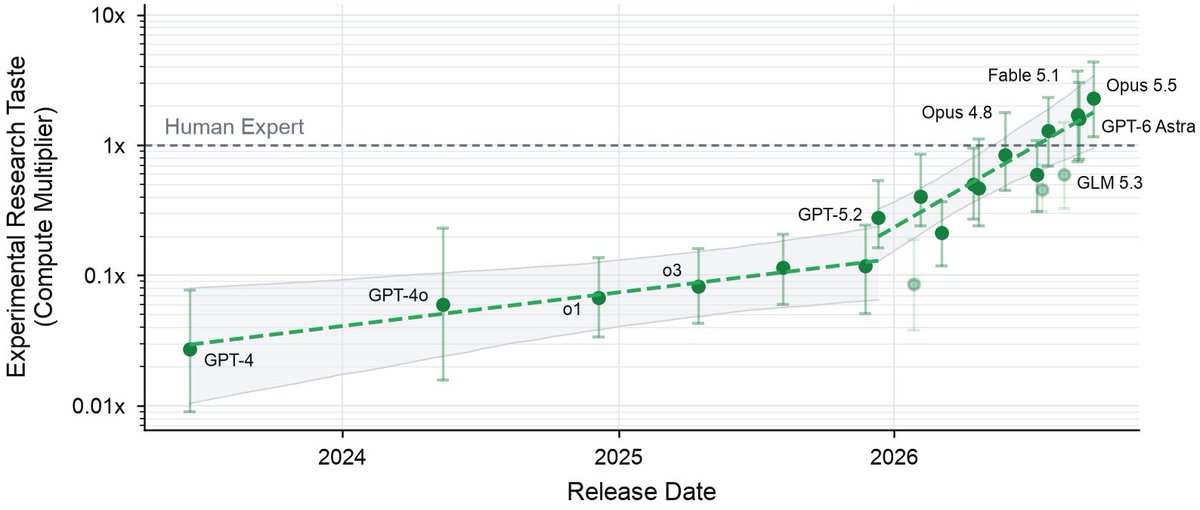
A post says TasteVal scores have doubled every 3.0 months since December 2025, following slower progress from 2023 through 2025.
TLDR
A post describes P-Zero Research's TasteVal as testing how well models design experiments and read results on eight real AI-development tasks, scored by the compute needed relative to human experts. It says scores have doubled every 3.0 months since December 2025 and puts Claude Opus 5.5 at 2.30x the expert baseline, ahead of Fable 5.1 and GPT-6 Astra, at roughly 1/30 of experts' cost per attempt.
Combined views
—
1 Source, first seen ago
— likes— comments— saves— reposts