AI
Brilliant’s AI tutor Koji switches to Wafer
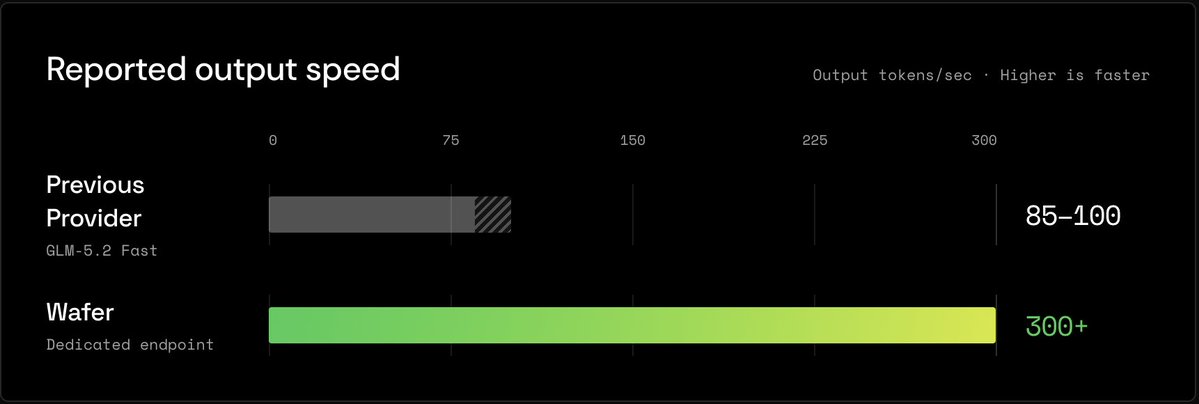
A Wafer team member says the move tripled throughput, letting Brilliant stop preparing AI responses in advance and cut inference costs by 50%.
TLDR
A Wafer team member says Brilliant’s math and coding tutor, Koji, now uses a dedicated GLM-5.2 endpoint that delivers its first token in roughly 250 milliseconds and generates 300-plus output tokens per second—three times its previous provider’s throughput. According to the account, that performance let Brilliant remove a prefetching layer, which prepared AI responses ahead of time so students wouldn’t have to wait, and cut inference costs by 50%.