AI
RRSI reportedly ranks first on three held-out benchmarks among five agent-harness methods
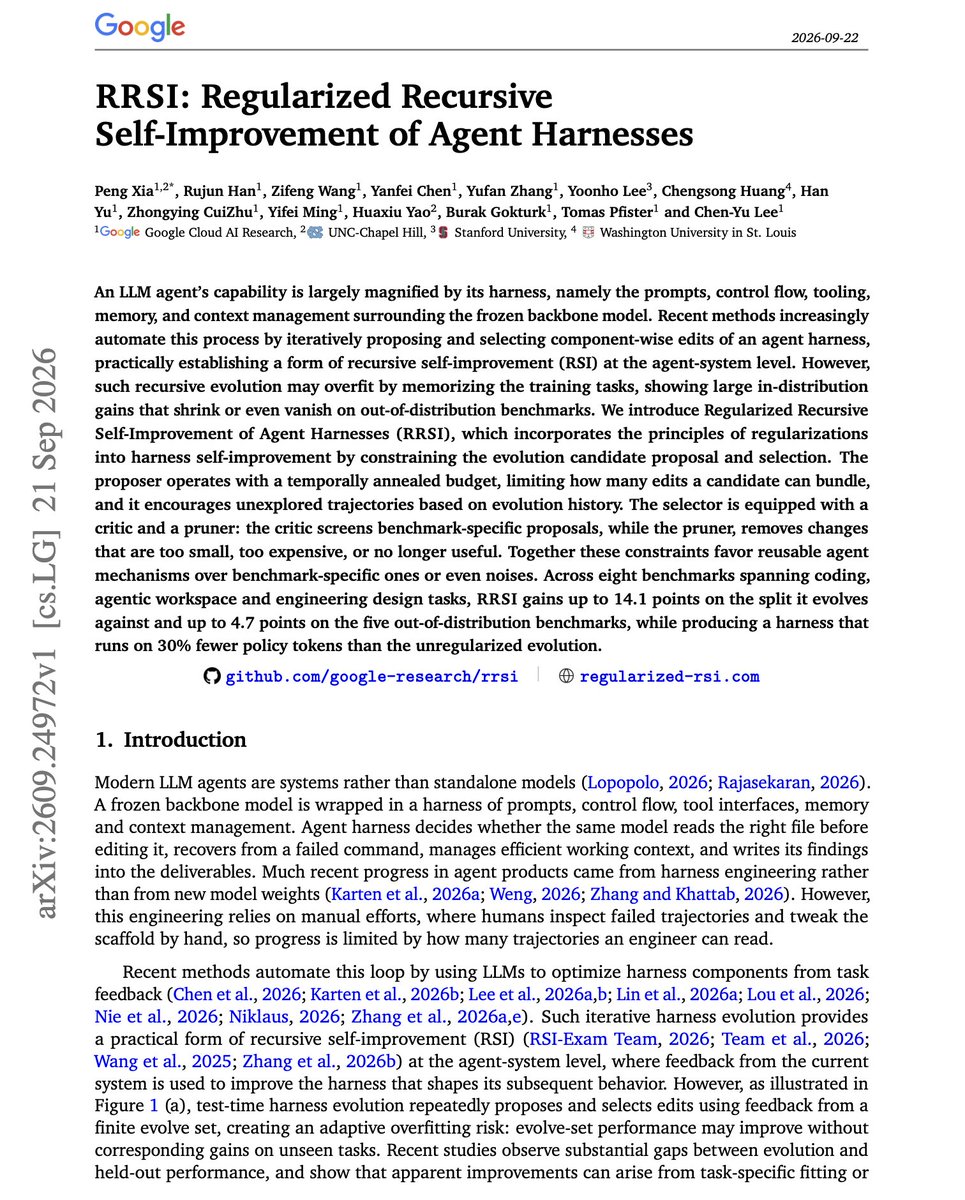
A post summarizing a Google paper says RRSI scored lowest on the tasks used to tune agent harnesses—the prompts, tools, memory and control flow around an agent—but highest on three held-out benchmarks.
TLDR
According to a post summarizing a Google paper, automatically editing an agent’s harness to raise evaluation scores can overfit the tuning tasks rather than improve performance elsewhere. RRSI addresses this with a shrinking edit budget, encouragement to explore untried directions, a critic that rejects benchmark-specific edits, and pruning of changes that are too small, too costly or no longer useful. The post reports that RRSI scored 90.5 on the Harvey LAB evolve split and gained 3.5–4.7 points on JobBench, GDPval and APEX-Agents. Meta-Harness scored 93.0 on the evolve split but gained only 0.3–1.5 points on those benchmarks. In an ablation, the post says RRSI used 2.42 million tokens per trial, versus 3.80 million for unregularized evolution.