• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
AI

SGLang adds 4-bit NVFP4 KV cache support for Nvidia Blackwell

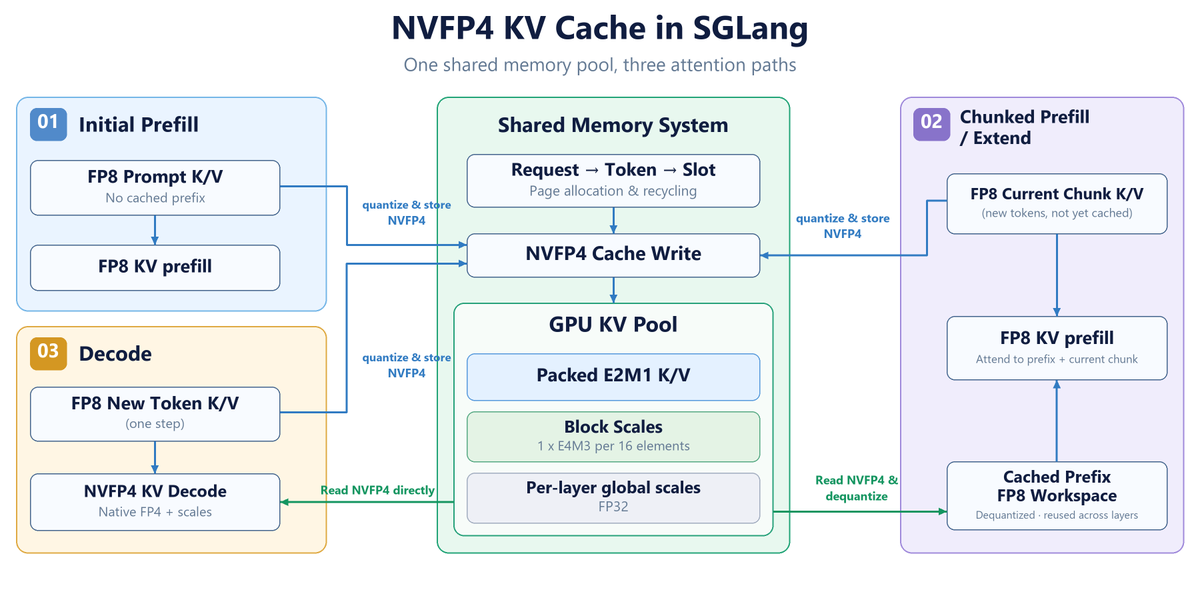
LMSYS says the cache uses about 56% of FP8's memory footprint per token and boosts long-context decoding throughput by up to 78%.

2 Sources, 20d ago, first seen 20d ago

TLDR

LMSYS announced NVFP4 KV cache support in SGLang for Nvidia Blackwell, developed with Alibaba's Qwen team and Nvidia. It reports decoding throughput gains of 37%, 58% and 78% at context lengths of 32K, 160K and 1M, respectively. LMSYS also says accuracy matched FP8 on GPQA-Diamond and AIME 2025 using Qwen3.5-397B-A17B. The cache can be enabled in SGLang with the flag --kv-cache-dtype nvfp4.

Combined views

—

2 Sources, first seen 20d ago

— likes— comments— saves— reposts

Combined views

—

2 Sources, first seen 20d ago

— likes— comments— saves— reposts

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

Featured Source

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

2 Sources

LMSYS Org@lmsysorg🚀New blog: Accelerating Long-Context and Agentic Inference with NVFP4 KV Cache 4-bit KV cache is here! NVFP4 KV in SGLang packs ~1.78× more context into GPU memory and speeds up long-context decode by up to 78%. Together with @Alibaba_Qwen and @nvidia, we brought NVFP4 KV cache to Blackwell: - NVFP4 stores KV in just ~56% of FP8's footprint per token -️ Decode throughput jumps +37% / +58% / +78% at 32K / 160K / 1M context - Near-lossless accuracy: matches FP8 on GPQA-Diamond & AIME 2025 (Qwen3.5-397B-A17B) - Higher cache hit rate keeps AgentX throughput scaling where FP8 drops off The whole recipe combines NVFP4 two-level scaling, in-kernel dequantization on decode, and paged KV cache, and you can enable it in SGLang with a single flag --kv-cache-dtype nvfp420d
Banghua Zhu@BanghuaZRT @lmsysorg: 🚀New blog: Accelerating Long-Context and Agentic Inference with NVFP4 KV Cache 4-bit KV cache is here! NVFP4 KV in SGLang pa…20d
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI

    2 Sources

    LMSYS Org@lmsysorg🚀New blog: Accelerating Long-Context and Agentic Inference with NVFP4 KV Cache 4-bit KV cache is here! NVFP4 KV in SGLang packs ~1.78× more context into GPU memory and speeds up long-context decode by up to 78%. Together with @Alibaba_Qwen and @nvidia, we brought NVFP4 KV cache to Blackwell: - NVFP4 stores KV in just ~56% of FP8's footprint per token -️ Decode throughput jumps +37% / +58% / +78% at 32K / 160K / 1M context - Near-lossless accuracy: matches FP8 on GPQA-Diamond & AIME 2025 (Qwen3.5-397B-A17B) - Higher cache hit rate keeps AgentX throughput scaling where FP8 drops off The whole recipe combines NVFP4 two-level scaling, in-kernel dequantization on decode, and paged KV cache, and you can enable it in SGLang with a single flag --kv-cache-dtype nvfp420d
    Banghua Zhu@BanghuaZRT @lmsysorg: 🚀New blog: Accelerating Long-Context and Agentic Inference with NVFP4 KV Cache 4-bit KV cache is here! NVFP4 KV in SGLang pa…20d
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet